Jiajun Fan

Research

Projects

One page per paper: the idea, the evidence, a short film and the BibTeX.

2026 10 projects * first or co-first author

PinnedPreprint 2026

Language Models Can Rewrite Their Own Weights

J. Fan*, N. He, C. Yang, A. Mao, X. Zhu, C. Cheng, K. Liang, S. Shen, Z. Li, R. Guo, G. Liu

A third way to make a model better

For the first time, to our knowledge, a language model rewrites its own weights by its own reasoning and becomes better, with no gradients and no training: the model is its own optimizer. It surpasses itself on problems it never saw, keeps getting better session after session, and repairs a damaged copy of itself without ever seeing its original weights.
Preprint 2026

Keystone: Judging Previews at Key Steps for Test-Time Search in Diffusion Models

J. Fan*, C. Cheng, Z. Wang, C. Yang, B. Yang, Q. Zheng, G. Liu

Judge the image at its beginning

An image model decides what it will draw in its first steps. Keystone judges candidates there, from the model’s own blurry previews, with an off-the-shelf decision model asked the prompt’s own questions, so test-time search stops finishing images that were doomed from the start.

Preprint 2026

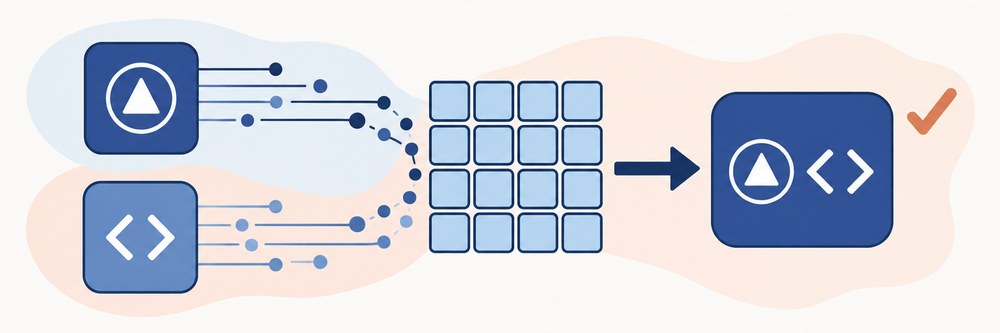
Vanguard: Knowing When to Trust the Draft in Speculative Vision-Language Agents

H. Mao*, J. Fan*, R. Guo, S. Shen, Z. Wang, H. Ren, X. Zhong, G. Liu

A small draft that leads its large target

Let a small model go first: a decision model checks each drafted step of an agent against the screen, keeps it when confident and calls the large model only when needed. Training-free, across model families, and more accurate than the large model alone on web and household tasks.

Preprint 2026

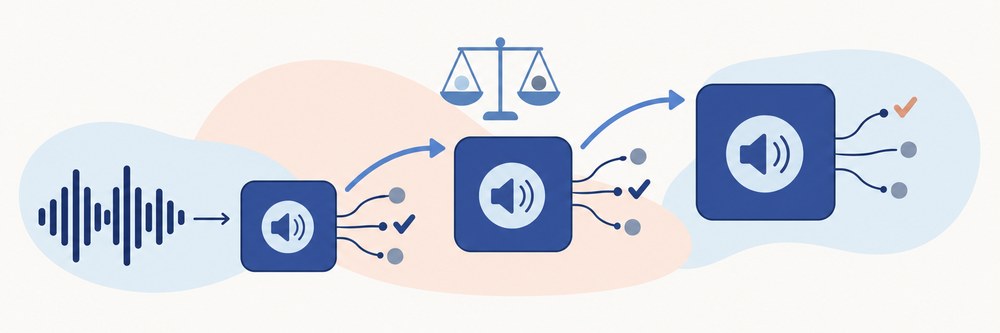
AudioRSI: Recursively Self-Improving Audio Reasoners

J. Fan*, R. Ren, J. Li, R. Pandey, P.G. Shivakumar, A. Gandhe, Y. Gu, G. Liu, I. Bulyko

Surpasses its teacher, then becomes it

One model is both student and teacher. To our knowledge, the first recursively self-improving audio LLM: 76.1% on MMAU test-mini at 7B, with no external reward model.

Preprint 2026

Training-Free On-Policy Distillation

B. Yang*, J. Fan*, Z. Zhu, H. Ma, G. Liu

Zero gradient steps, best mean accuracy

RL specialists that share a base model merge into one model with forward passes only, and the merged model is on average more accurate than either specialist.

Preprint 2026

SpeechGym: Training Voice Agents with RL

J. Fan*, J. Li, P.G. Shivakumar, J-H. Huang, Q. Luo, M. Maruf, I. Bulyko, G. Liu, R. Ren

τ-Voice task success 24% → 53%

Voice agents could be measured, never improved. Both sides speak natively and locally, so the agent can be trained end to end.

Preprint 2026

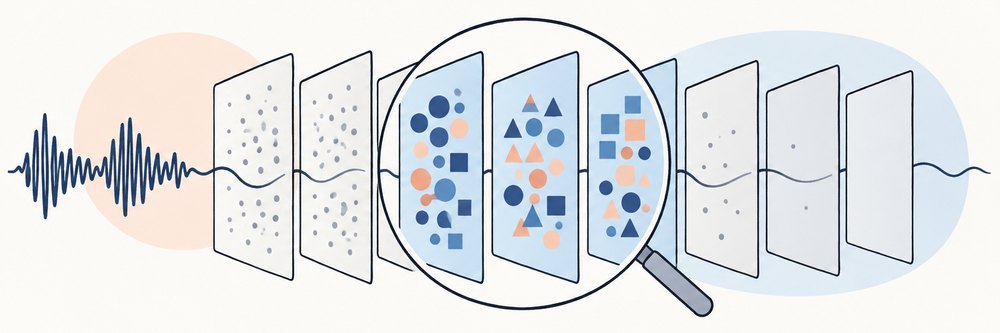
Can We Read the Mind of an Audio LLM?

J. Fan*, J. Li, P.G. Shivakumar, Q. Luo, J-H. Huang, M. Maruf, R. Ren, Y. Gu, R. Pandey, G. Liu, I. Bulyko

the answer is legible before the first token

A verbalizable, multilingual middle-layer workspace — read with a logit lens at the audio-token positions.

2025 3 projects

2022 – 2023 2 projects

ICLR 2023

LBC: Breaking 24 Atari World Records

J. Fan*, Y. Zhuang, Y. Liu, J. Hao, B. Wang, J. Zhu, H. Wang, S.-T. Xia

10,077% HNS · 24 records · 100× data efficient

Learnable behavior control via hybrid behavior mapping + bandit meta-controller.