
Strong, fixed
one large β for every sample
Safe, but the reward barely moves.
- Reaches high reward
- Keeps its samples varied
At a glance
Reinforcement learning fine-tuning keeps a generative model near where it started with one fixed penalty, the same for every sample. What if each sample set its own? ADRPO loosens it for samples better than their batch and tightens it for worse ones.
Fine-tuned with ADRPO, SD3 tops SANA-1.5 and FLUX.1-Dev on all six metrics.
Finding 02Fixed regularization trades one for the other. ADRPO leads both, and stays closest to SD3.
Finding 03In a language model it narrows its search, then widens it again, and ends with 5× GRPO’s reward.
Finding 04On MMAU audio reasoning, the same rule also beats GRPO.
The problem
Strong regularization keeps what the model could do but limits how far the reward can rise. Weak regularization lets the reward rise but risks collapse and reward hacking. PPO, GRPO and DPO all pick one strength and use it for every sample.
one large β for every sample
Safe, but the reward barely moves.
one small β for every sample
The reward climbs, and the samples collapse into one.
β0 − A, set by each sample
The reward climbs, and the samples stay varied.
A good sample and a bad one are held back exactly the same.
The idea Adaptive regularization
A is the sample’s advantage: how much its reward beats the average of its batch. The model may move further toward good samples, and stays close to where it started on poor ones.
The advantage is the signal the update already uses. ADRPO reads it a second time to set the regularization.
Exploit where the samples are good, stay careful where they are not.
How it works
In GRPO, only the fixed β changes: it becomes β0 − A. On flow models, the reward weight also becomes the advantage.
Online fine-tuning of SD3; the divergence compares its velocity field with the pre-trained one.
Fixed: ORW-CFM-W2L = LORW + β · ‖vθ − vref‖2
ADRPOL = LRL + (β0 − A) · ‖vθ − vref‖2
LRL weights each sample by its advantage, so poor samples are pushed away rather than only weighted down.
GRPO fine-tuning of an LLM or a multimodal reasoning model; the divergence is the KL to the reference model.
Fixed: GRPOL = LPG + β · DKL(πθ ‖ πref)
ADRPOL = LPG + (β0 − A) · DKL(πθ ‖ πref)
A is GRPO’s own group advantage; β0 equals the fixed β it replaces.
Nothing new to train, and no schedule to tune.
The evidence Finding 01
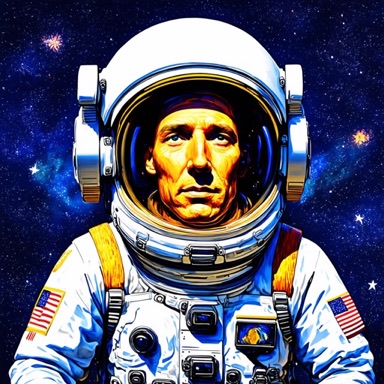
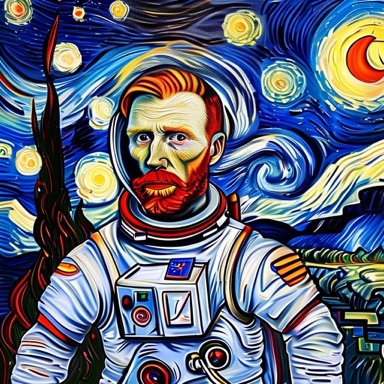
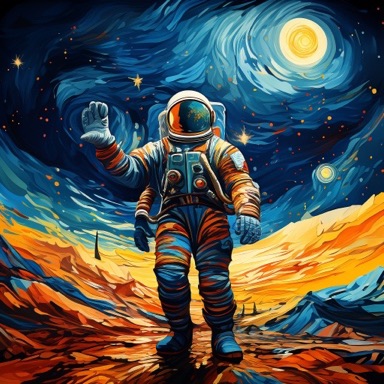
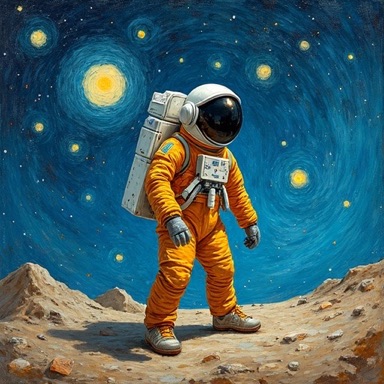
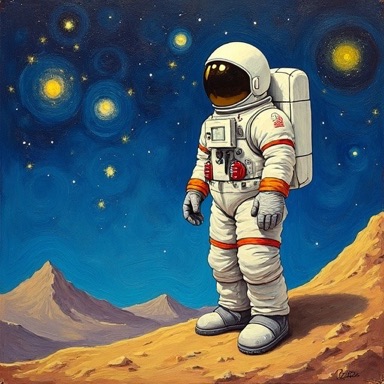
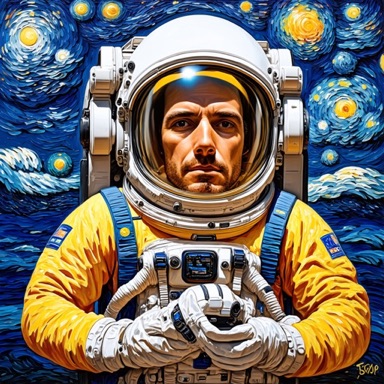
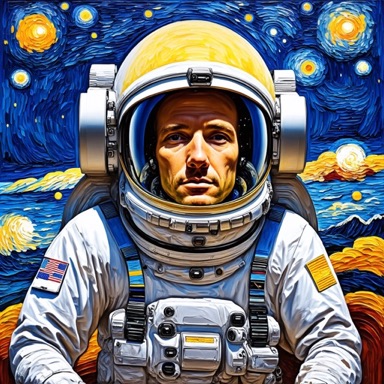
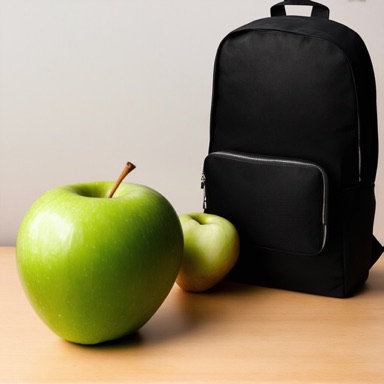
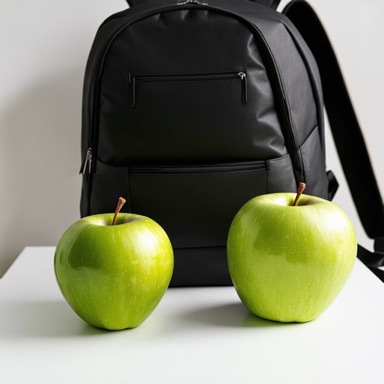
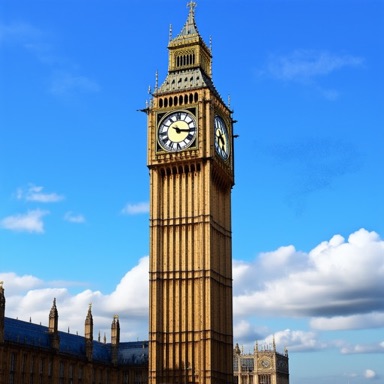
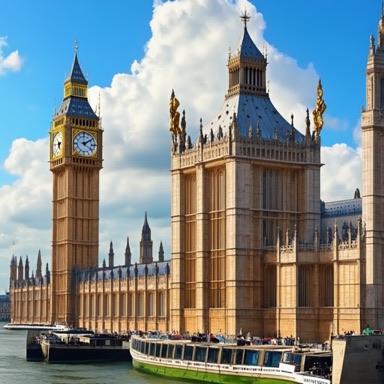
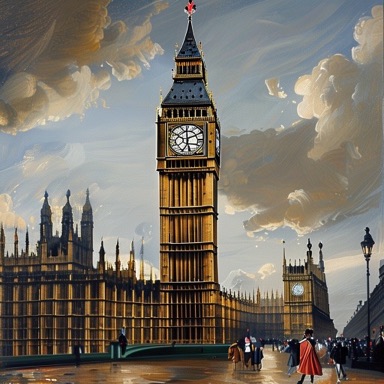
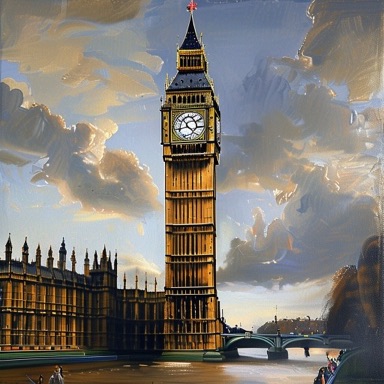
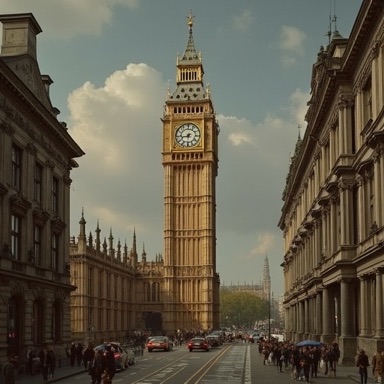
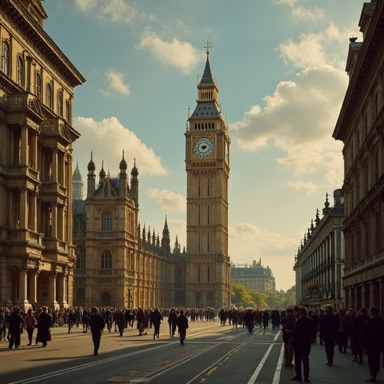
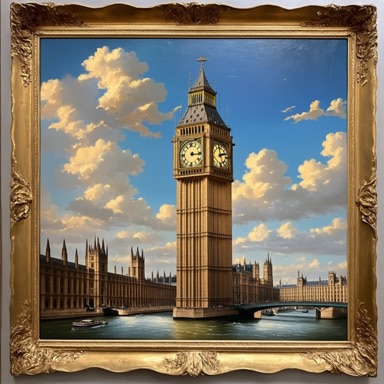
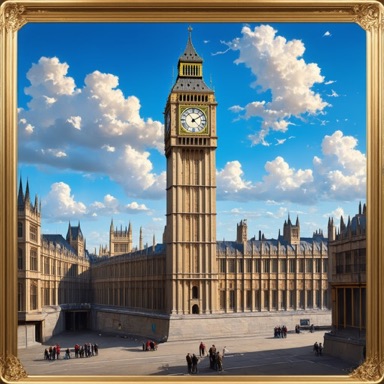
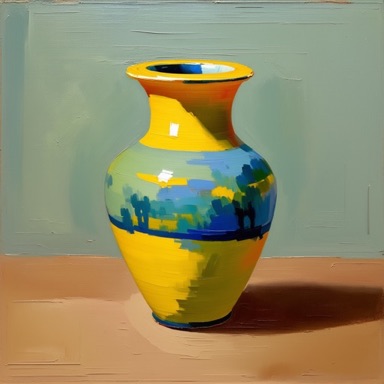
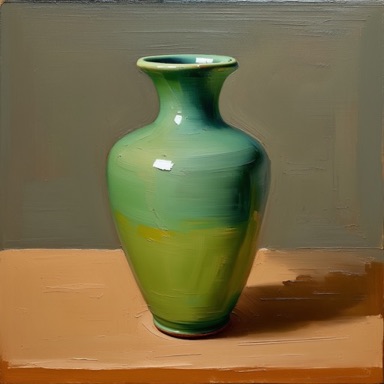
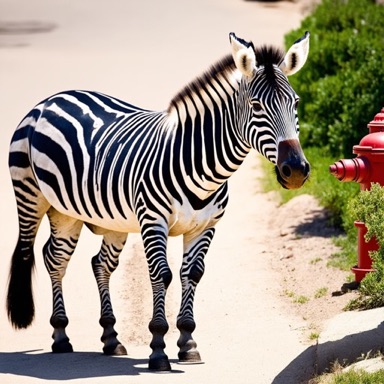
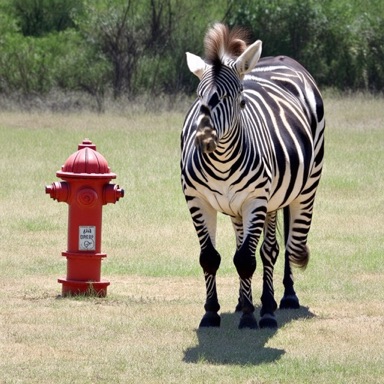
Fine-tuned with ADRPO, SD3 (2B) scores above SANA-1.5 (4.8B) and FLUX.1-Dev (12B) on all six metrics, and keeps the styles, colors and layouts the prompts ask for.
PromptVan Gogh style astronaut
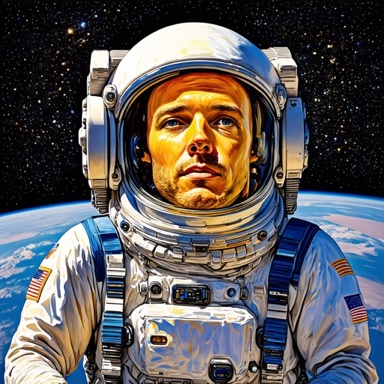
PromptA green apple and a black backpack.
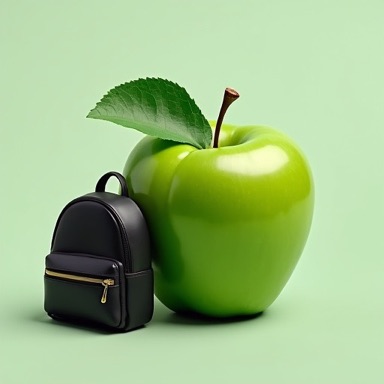
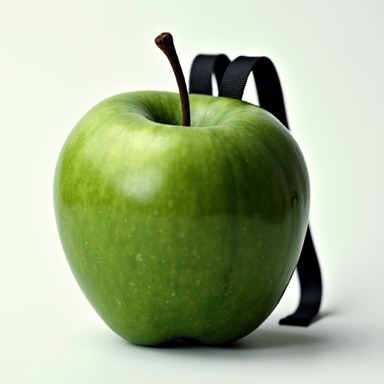
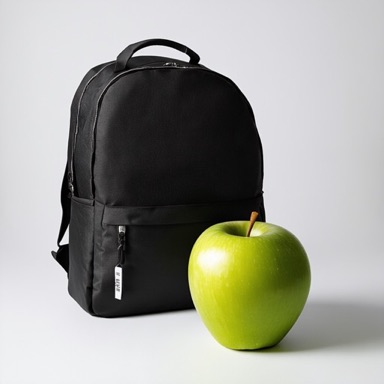
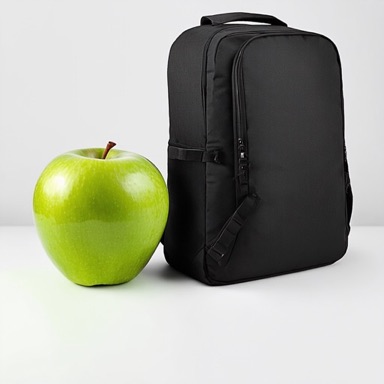
PromptJacques-Louis David style big ben
PromptEdward Hopper style vase
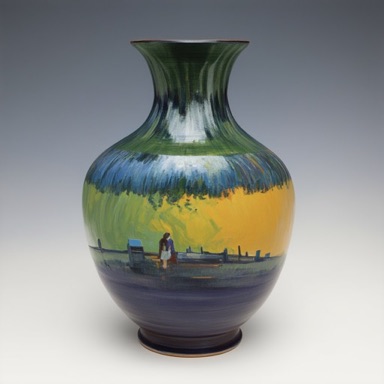
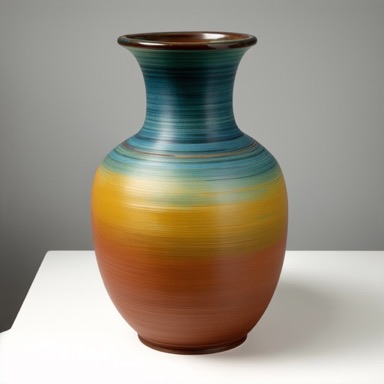
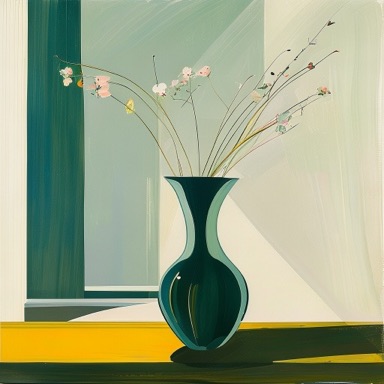
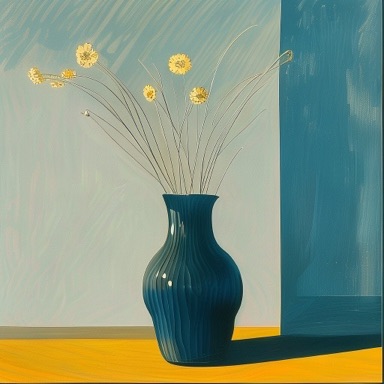
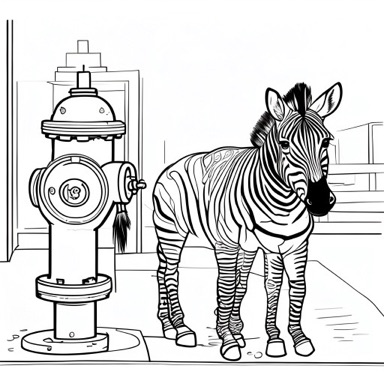
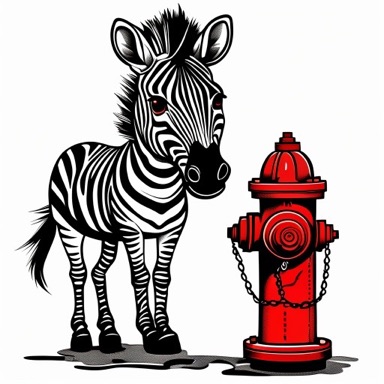
PromptA zebra to the right of a fire hydrant.
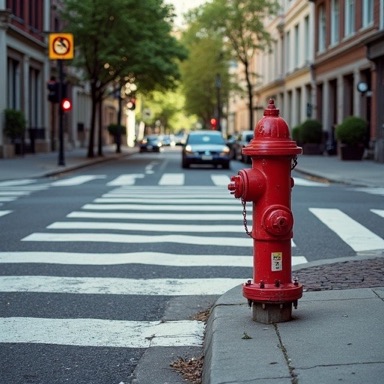
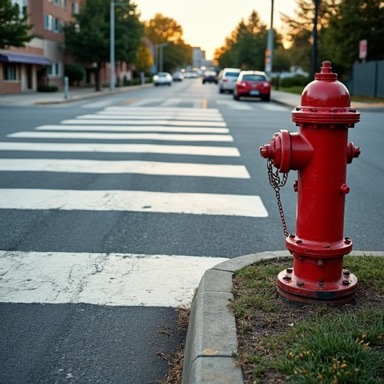
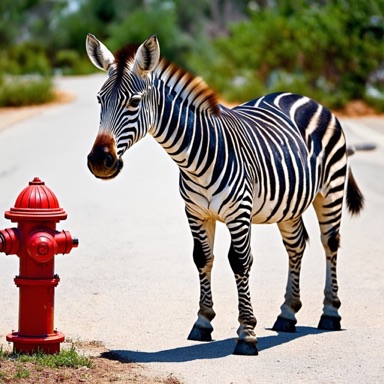
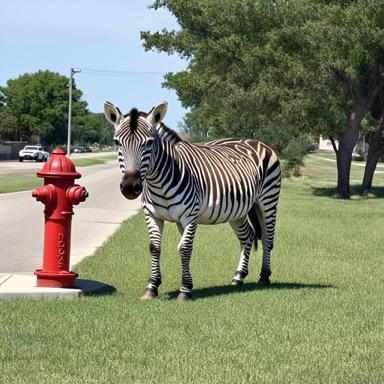
PromptA stack of 3 cubes. A red cube is on the top, sitting on a red cube. The red cube is in the middle, sitting on a green cube. The green cube is on the bottom.
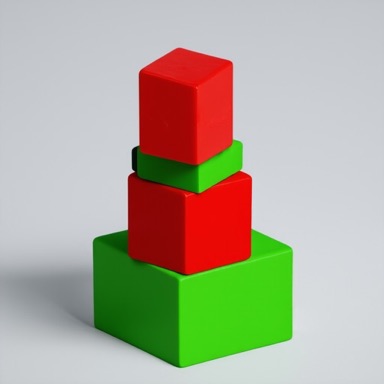
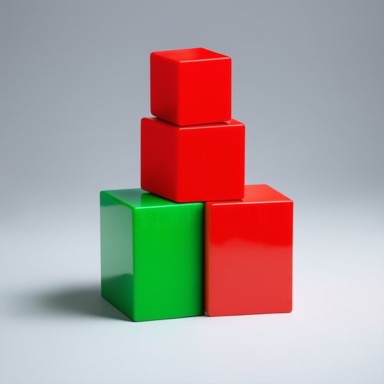
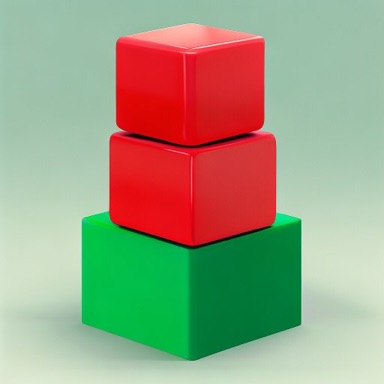
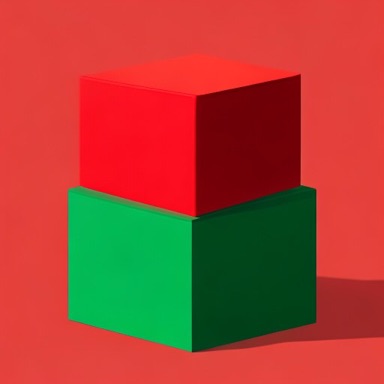
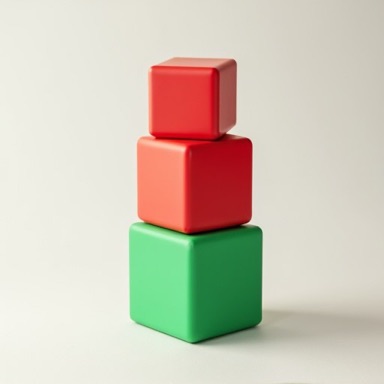
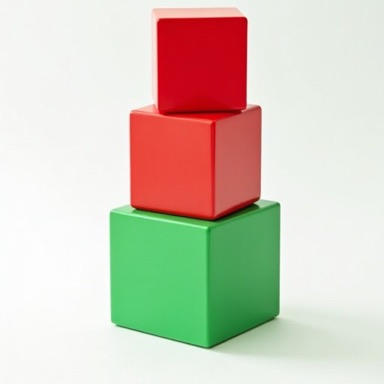
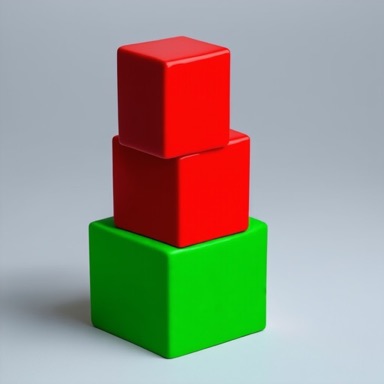
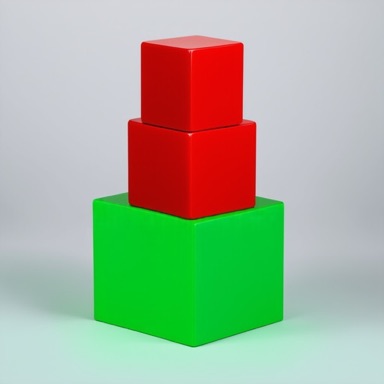
Samples from Figures 1 and 5 of the paper. Prompts from DrawBench and RAFT, and compositional prompts written for the paper.
Mean over 3 seeds (Table 1). Higher is better on every metric; each panel has its own scale.
How a model is fine-tuned can matter more than how big it is.
The evidence Finding 02
DPO stalls, and ORW-CFM-W2 buys its reward with diversity. ADRPO climbs highest, keeps its samples varied and stays closest to SD3.
Paths: checkpoints during training, one seed, read from Figure 3 of the paper. Dots: final scores, mean over 3 seeds (Table 1).
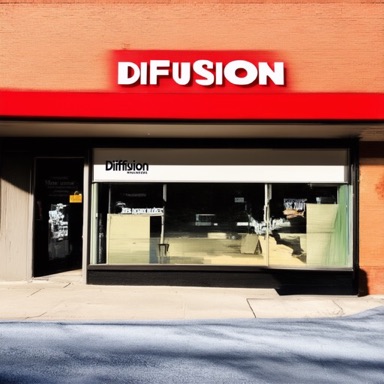
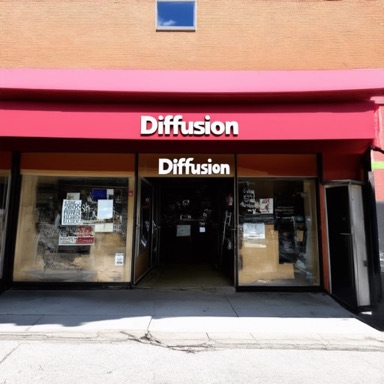
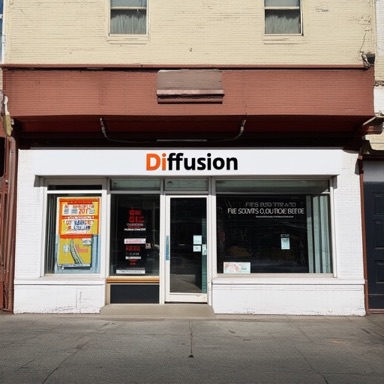
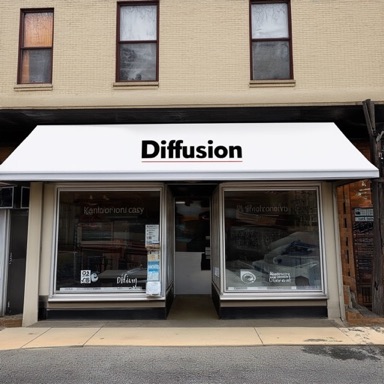
PromptA storefront with ‘Diffusion’ written on it.
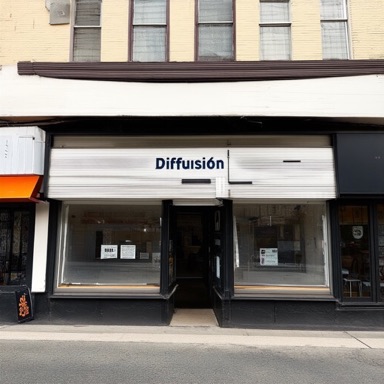
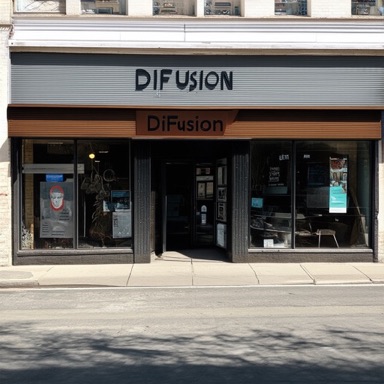
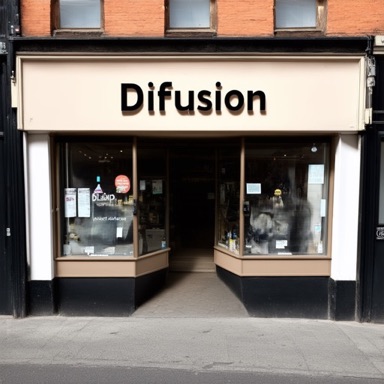
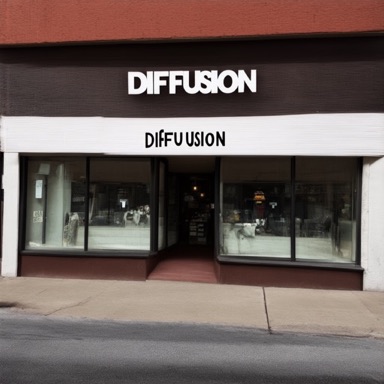
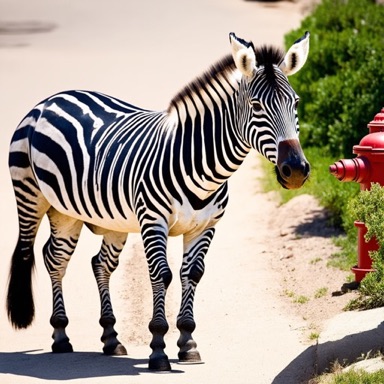
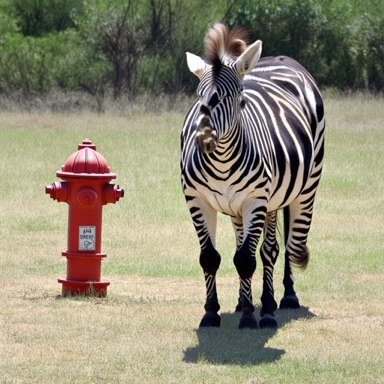
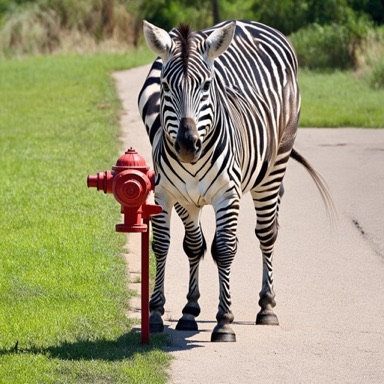
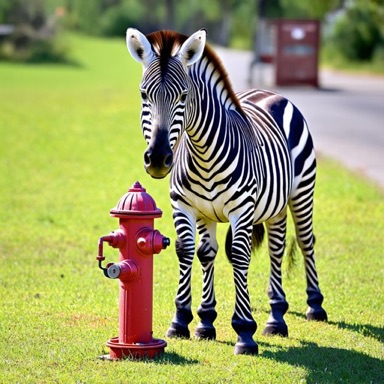
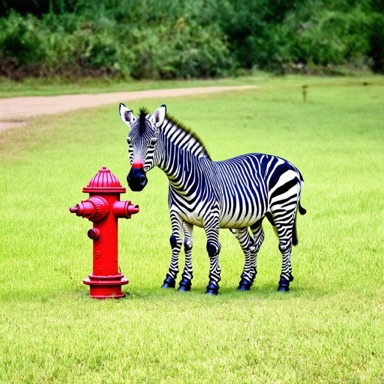
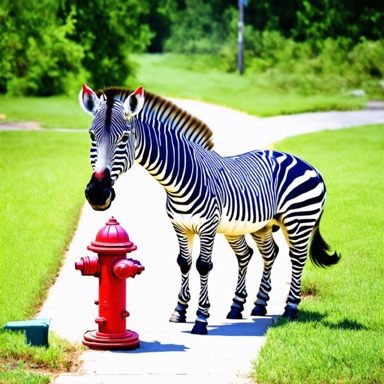
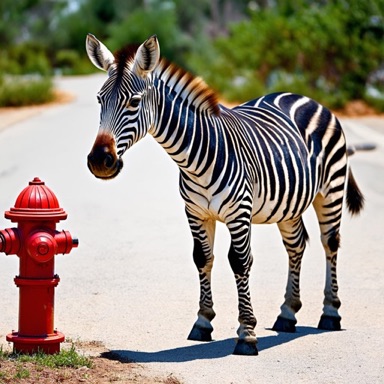
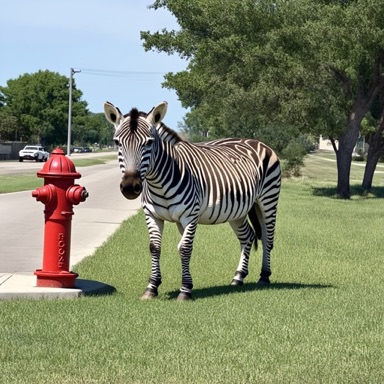
PromptA zebra to the right of a fire hydrant.
PromptA black colored banana
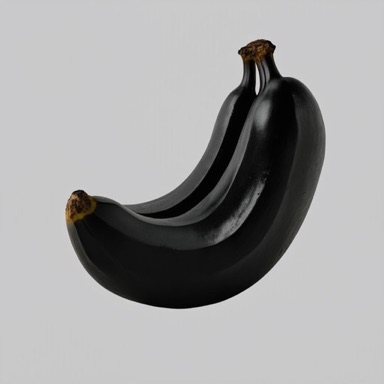
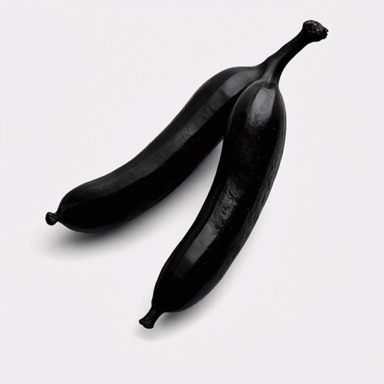
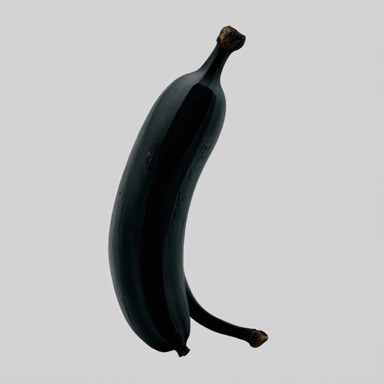
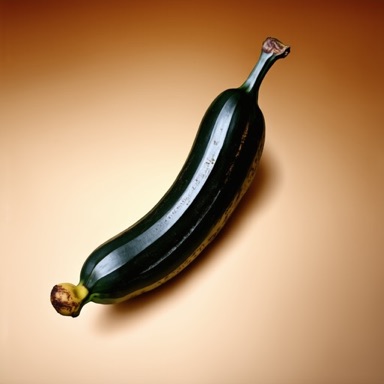
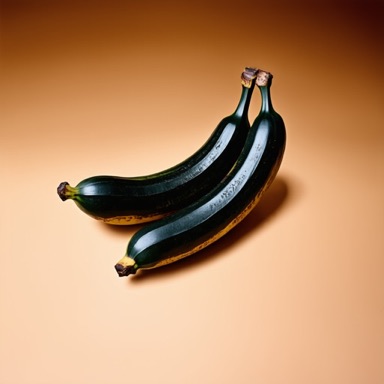
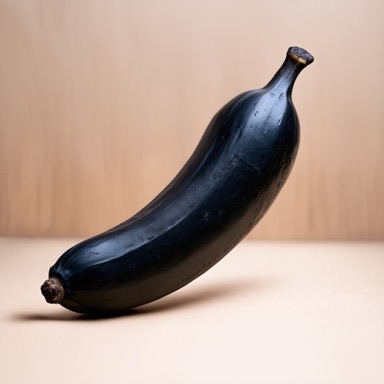
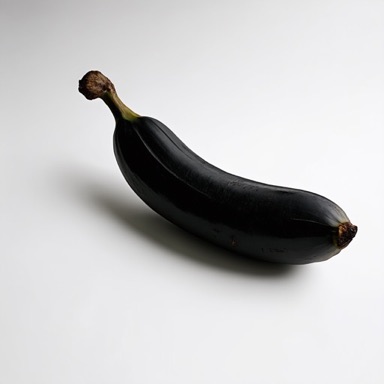
PromptEdward Hopper style vase
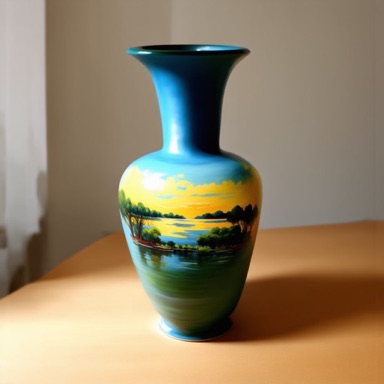
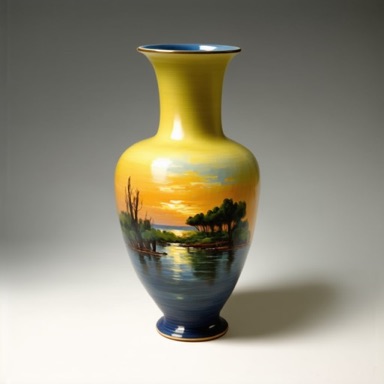
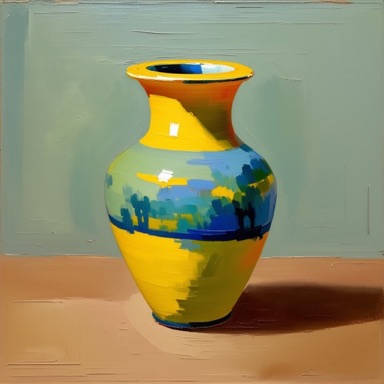
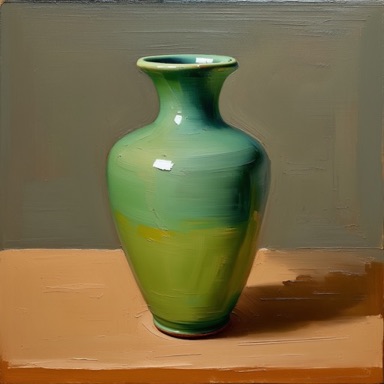
Samples from Figure 2 of the paper. ORW-CFM-W2’s two samples often look alike; ADRPO’s get the text, the position and the color right and still differ.
No trade between reward and diversity.
The evidence Finding 03
Plugged into GRPO to fine-tune Qwen3 (0.6B), ADRPO first narrows its outputs, then widens them again to climb out. GRPO stays at high entropy and struggles to find higher reward.
Each dot is a checkpoint during training, read from Figure 4 of the paper; the lines are running averages. Reward from the RM-Gemma-2B reward model on held-out prompts; entropy measures how widely the model explores.
It explores more when it is stuck, without being told to.
The evidence Finding 04
Fine-tuned on AVQA and tested on MMAU, Qwen2.5-Omni-7B with ADRPO answers more audio questions right than with GRPO, and more than both commercial models.
Temporal sequenceWhat was the last sound in the sequence?footsteps, dog barking, camera shutter clicking, tapping on glass
Camera shutter clicking, wrongTapping on glass, correctSource identificationBased on the given audio, identify the source of the flowing water.Bathtub, River, Fountain, Rain
Fountain, wrongBathtub, correctContextual reasoningConsidering the information in the audio, what type of weather condition can be inferred?Windy, Calm, Rainy, Snowy
Rainy, wrongWindy, correctAccuracy from Table 2; reasoning from Table 5 of the paper, both models fine-tuned from Qwen2.5-Omni-7B.
It keeps reasoning where GRPO settles too early.
Why it matters
ADRPO plugs into the reinforcement learning fine-tuning people already run, for continuous and discrete models alike.
Flow matching on SD3, with W2 regularization.
beats 4.8B and 12B modelsGRPO on Qwen2 and Qwen3, with KL regularization.
escapes a local optimumGRPO on Qwen2.5-Omni-7B, with KL regularization.
beats Gemini 2.5 ProA small model fine-tuned well can stand with much larger ones, and it costs less to run.
The advantage tells the model when to stay close and when to move on, so it can climb out of a local optimum.
One coefficient becomes a function of the advantage. In GRPO, nothing else changes.
The film
Opens the film page.
Cite
Conference on Neural Information Processing Systems 2025 (NeurIPS 2025).
@inproceedings{fan2025adaptive,
  title     = {Adaptive Divergence Regularized Policy Optimization
  for Fine-tuning Generative Models},
  author    = {Jiajun Fan and Tong Wei and Chaoran Cheng and Yuxin Chen and Ge Liu},
  booktitle = {The Thirty-ninth Annual Conference on Neural Information Processing Systems},
  year      = {2025},
  url       = {https://openreview.net/forum?id=aXO0xg0ttW}
}