I am a CS Ph.D. student at UIUC, where I study how to train multimodal large generative/agentic models with reinforcement learning in a way that is stable (e.g., lifelong continual learning) — avoiding the diversity and performance collapse that RL fine-tuning tends to cause — and progressively autonomous (e.g., recursive self-improvement, RSI), step by step taking the human out of the loop: first human data collection, then human labelling and hyper-parameter tuning, and finally hand-designed rewards. That work spans these domains:
Seeking research internship — Fall 2026 / 2027. RL · Generative Models · Reasoning LLMs · Agentic RL [CV][Scholar][Email]
Latest News
Oct 2026TalkGave a talk at the IGB (Lunch with CNRG) on building LLM post-training projects with an AI coding agent. Always happy to give talks on LLM post-training with RL and on AI scientists — agentic methods for automated scientific discovery — just reach out. Event
Oct 2026CodeProteinZero (TMLR 2026) is now open source — feel free to use it, for example as a tool in your own agent or design pipeline, and I am always happy to discuss collaborations. Project page · Code
Sep 2026AcceptMultiple papers accepted at NeurIPS 2026. See you in Atlanta
Sep 2026AcceptPaper accepted at IEEE TMM (Transactions on Multimedia).
Aug 2026FindingVoice agents could be measured, never improved — so we closed the loop and trained one in native audio. Blog · Paper
Aug 2026FindingFor the first time, we can see the brain map of an Audio LLM — its global workspace, the “consciousness space”. Blog · Paper
Jul 2026AcceptProteinZero accepted at TMLR — first online-RL framework for self-improving protein generation. Project page
Training tool-augmented large language models has evolved from supervised fine-tuning (SFT) to reinforcement learning with verifiable rewards (RLVR). Yet existing methods rarely examine whether intermediate execution logic—specifically, the procedural fidelity of multi-turn tool invocations—requires explicit supervision. We hypothesize that enforcing sequential validity at the turn level is a prerequisite for robust multi-turn task completion. To this end, we introduce a Procedure-Aware Reinforcement Learning Framework that explicitly evaluates procedural validity through both invocation chain quality and final system state correctness. Using Group Relative Policy Optimization (GRPO) with KL regularization to fine-tune Qwen2.5-3B-Instruct, we demonstrate on API-Bank, Bamboogle, and BFCL-V3 that our approach consistently outperforms correctness-only baselines. Despite operating at a substantially smaller scale, our 3B model achieves average accuracy competitive with proprietary models such as GPT-5-mini, GPT-4.1-mini, Claude-Haiku-4.5, and Gemini-2.5-Flash-Lite, whose scores are obtained under BFCL’s official per-model evaluation protocols. Qualitative analysis reveals that optimizing tool sequencing yields emergent benefits, simultaneously enhancing multi-turn performance and error recovery from failed tool calls.
Q. Zheng*, J. Fan*, C. Cheng, G. Liu
Procedure-Aware RL: a procedural reward and an error-aware penalty on top of GRPO, so tool-using agents learn to order their calls.
3B model competitive with GPT-5-mini and Claude-Haiku-4.5 on BFCL-V3
Protein generative models have shown remarkable promise in protein design, yet their success rates remain constrained by reliance on curated sequence-structure datasets and by misalignment between supervised objectives and real design goals. We present ProteinZero, an online reinforcement learning framework for inverse folding models that enables scalable, automated, and continuous self-improvement with computationally efficient feedback. ProteinZero employs a reward pipeline that combines structural guidance from ESMFold with a novel self-derived ddG predictor, providing stable multi-objective signals while avoiding the prohibitive cost of physics-based methods. To ensure robustness in online RL, we further introduce a novel embedding-level diversity regularizer that mitigates mode collapse and promotes sequence-level diversity among generated designs. Within a general RL formulation balancing multi-reward optimization, KL-divergence from a reference model, and diversity regularization, ProteinZero achieves robust improvements across designability, predicted stability, recovery, and diversity. On the CATH-4.3 benchmark, it consistently outperforms state-of-the-art baselines including ProteinMPNN, ESM-IF, and InstructPLM, reducing design failure rates by 36-48% and achieving success rates above 90% across diverse folds. Importantly, a complete RL run can be executed on a single 8xGPU node within three days, including reward computation and data generation. These results indicate that efficient online RL fine-tuning can complement supervised pretraining by allowing protein generative models to evolve continuously from their own outputs and optimize multiple design objectives without labeled data, opening new possibilities for exploring the vast protein design space. Code and model checkpoints are available at https://github.com/ziwenwang28/ProteinZero.
Z. Wang*, J. Fan*, R. Guo, T. Nguyen, H. Ji, G. Liu
ProteinZero: online RL for protein design — the model keeps improving from its own generations while staying diverse.
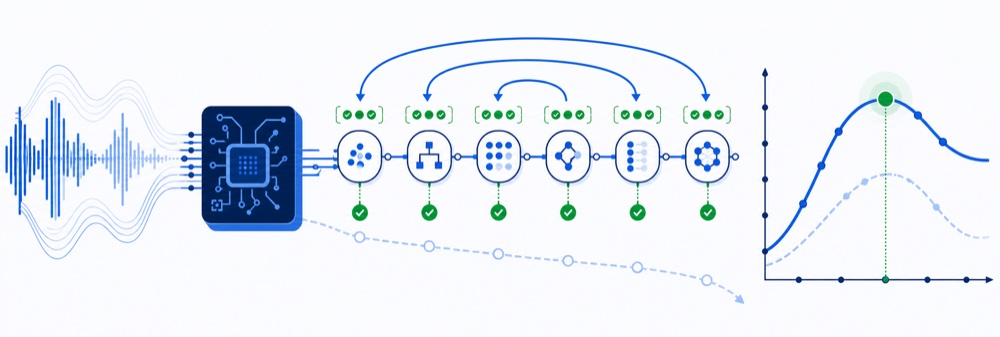
The role of reasoning in Audio Large Language Models remains widely underexplored, as introducing a reasoning process often degrades rather than improves performance during inference, a phenomenon we term test-time inverse scaling, where longer reasoning chains yield progressively worse results. We demonstrate that this stems not from fundamental limitations of reasoning itself, but from inadequate training: models without proper guidance for the reasoning process produce hallucinatory, inconsistent reasoning that accumulates errors over longer chains. To address these challenges, we introduce CESAR (Consistent, Effective, and Scalable Audio Reasoners), shifting from outcome verification to rewarding the reasoning process. Our online reinforcement learning framework employs Group Relative Policy Optimization with a multi-faceted reward suite that incentivizes not only correctness and format but also consistency, structured analytical patterns, causal reasoning, domain-knowledge integration, and calibrated reasoning depth. CESAR resolves test-time inverse scaling, transforming reasoning from detriments into gains while revealing model-specific ``reasoning sweet spots", where performance peaks during test-time scaling. We achieve state-of-the-art results on MMAU Test-mini, substantially outperforming Gemini 2.5 Pro and GPT-4o Audio, and near-human-level performance on MMSU reasoning tasks. Through AI-as-judge evaluations and qualitative comparisons, we provide both quantitative and qualitative validation of our improved reasoning quality. Importantly, enhanced reasoning creates synergistic effects, simultaneously improving multimodal reasoning and perception capabilities. Overall, CESAR establishes a principled method for developing robust and scalable reasoning in Audio LLMs.
J. Fan*, R. Ren, J. Li, R. Pandey, P.G. Shivakumar, I. Bulyko, A. Gandhe, G. Liu, Y. Gu
CESAR: process-reward RL (GRPO) resolving test-time inverse scaling in Audio LLMs — models produce hallucinatory reasoning without proper guidance; CESAR fixes that.
SOTA on MMAU Test-mini · Outperforms Gemini 2.5 Pro & GPT-4o Audio
Vision-Language-Action (VLA) models have attracted increasing attention for their strong control capabilities. However, their high computational cost and low execution frequency hinder their suitability for real-time tasks such as robotic manipulation and autonomous navigation. Existing VLA acceleration methods primarily focus on structural optimization, overlooking the fact that these models operate in sequential decision-making environments. As a result, temporal redundancy in sequential action generation and spatial redundancy in visual input remain unaddressed. To this end, we propose SP-VLA, a unified framework that accelerates VLA models by jointly scheduling models and pruning tokens. Specifically, we design an action-aware model scheduling mechanism that reduces temporal redundancy by dynamically switching between VLA model and a lightweight generator. Inspired by the human motion pattern of focusing on key decision points while relying on intuition for other actions, we categorize VLA actions into deliberative and intuitive, assigning the former to the VLA model and the latter to the lightweight generator, enabling frequency-adaptive execution through collaborative model scheduling. To address spatial redundancy, we further develop a spatio-semantic dual-aware token pruning method. Tokens are classified into spatial and semantic types and pruned based on their dual-aware importance to accelerate VLA inference. These two mechanisms work jointly to guide the VLA in focusing on critical actions and salient visual information, achieving effective acceleration while maintaining high accuracy. Extensive experiments show that our method achieves 1.5× lossless acceleration in LIBERO and 2.4× in SimplerEnv, with up to 6% average performance gain. Inference frequency and latency improve by 2.2× in SimplerEnv and 1.4× in LIBERO.
Y. Li, Y. Meng, Z. Sun, K. Ji, C. Tang, J. Fan, X. Ma, S.-T. Xia, Z. Wang, W. Zhu
Action-aware model scheduling + spatio-semantic token pruning for VLA acceleration.
Balancing exploration and exploitation during reinforcement learning fine-tuning of generative models presents a critical challenge, as existing approaches rely on fixed divergence regularization that creates an inherent dilemma: strong regularization preserves model capabilities but limits reward optimization, while weak regularization enables greater alignment but risks instability or reward hacking. We introduce Adaptive Divergence Regularized Policy Optimization (ADRPO), which automatically adjusts regularization strength based on advantage estimates-reducing regularization for high-value samples while applying stronger regularization to poor samples, enabling policies to navigate between exploration and aggressive exploitation according to data quality. Our implementation with Wasserstein-2 regularization for flow matching generative models achieves remarkable results on text-to-image generation, achieving better semantic alignment and diversity than offline methods like DPO and online methods with fixed regularization like ORW-CFM-W2. ADRPO enables a 2B parameter SD3 model to surpass much larger models with 4.8B and 12B parameters in attribute binding, semantic consistency, artistic style transfer, and compositional control while maintaining generation diversity. ADRPO generalizes to KL-regularized fine-tuning of both text-only LLMs and multi-modal reasoning models, enhancing existing online RL methods like GRPO. In LLM fine-tuning, ADRPO demonstrates an emergent ability to escape local optima through active exploration, while in multi-modal audio reasoning, it outperforms GRPO through superior step-by-step reasoning, enabling a 7B model to outperform substantially larger commercial models including Gemini 2.5 Pro and GPT-4o Audio, offering an effective plug-and-play solution to the exploration-exploitation challenge across diverse generative architectures and modalities.
J. Fan*, T. Wei, C. Cheng, Y. Chen, G. Liu
ADRPO: sample-level adaptive divergence regularization — high-value samples get more freedom, poor samples get stronger constraint. Plug-and-play on top of any RLHF method.
Contrastive learning has proven to be highly efficient and adaptable in shaping representation spaces across diverse modalities by pulling similar samples together and pushing dissimilar ones apart. However, two key limitations persist: (1) Without explicit regulation of the embedding distribution, semantically related instances can inadvertently be pushed apart unless complementary signals guide pair selection, and (2) excessive reliance on large in-batch negatives and tailored augmentations hinders generalization. To address these limitations, we propose Variational Supervised Contrastive Learning (VarCon), which reformulates supervised contrastive learning as variational inference over latent class variables and maximizes a posterior-weighted evidence lower bound (ELBO) that replaces exhaustive pair-wise comparisons for efficient class-aware matching and grants fine-grained control over intra-class dispersion in the embedding space. Trained exclusively on image data, our experiments on CIFAR-10, CIFAR-100, ImageNet-100, and ImageNet-1K show that VarCon (1) achieves state-of-the-art performance for contrastive learning frameworks, reaching 79.36% Top-1 accuracy on ImageNet-1K and 78.29% on CIFAR-100 with a ResNet-50 encoder while converging in just 200 epochs; (2) yields substantially clearer decision boundaries and semantic organization in the embedding space, as evidenced by KNN classification, hierarchical clustering results, and transfer-learning assessments; and (3) demonstrates superior performance in few-shot learning than supervised baseline and superior robustness across various augmentation strategies. Our code is available at https://github.com/ziwenwang28/VarContrast.
Recent advancements in reinforcement learning (RL) have achieved great success in fine-tuning diffusion-based generative models. However, fine-tuning continuous flow-based generative models to align with arbitrary user-defined reward functions remains challenging, particularly due to issues such as policy collapse from overoptimization and the prohibitively high computational cost of likelihoods in continuous-time flows. In this paper, we propose an easy-to-use and theoretically sound RL fine-tuning method, which we term Online Reward-Weighted Conditional Flow Matching with Wasserstein-2 Regularization (ORW-CFM-W2). Our method integrates RL into the flow matching framework to fine-tune generative models with arbitrary reward functions, without relying on gradients of rewards or filtered datasets. By introducing an online reward-weighting mechanism, our approach guides the model to prioritize high-reward regions in the data manifold. To prevent policy collapse and maintain diversity, we incorporate Wasserstein-2 (W2) distance regularization into our method and derive a tractable upper bound for it in flow matching, effectively balancing exploration and exploitation of policy optimization. We provide theoretical analyses to demonstrate the convergence properties and induced data distributions of our method, establishing connections with traditional RL algorithms featuring Kullback-Leibler (KL) regularization and offering a more comprehensive understanding of the underlying mechanisms and learning behavior of our approach. Extensive experiments on tasks including target image generation, image compression, and text-image alignment demonstrate the effectiveness of our method, where our method achieves optimal policy convergence while allowing controllable trade-offs between reward maximization and diversity preservation.
J. Fan*, S. Shen, C. Cheng, Y. Chen, C. Liang, G. Liu
ORW-CFM-W2: first online RLHF for flow matching — no human data, no likelihood, no collapse. W2 regularization keeps generation diverse.
First online RLHF for flow matching · Collapse-free W2 regularization
Flow-based generative models have shown remarkable success in text-to-image generation, yet fine-tuning them with intermediate feedback remains challenging, especially for continuous-time flow matching models. Most existing approaches solely learn from outcome rewards, struggling with the credit assignment problem. Alternative methods that attempt to learn a critic via direct regression on cumulative rewards often face training instabilities and model collapse in online settings. We present AC-Flow, a robust actor-critic framework that addresses these challenges through three key innovations: (1) reward shaping that provides well-normalized learning signals to enable stable intermediate value learning and gradient control, (2) a novel dual-stability mechanism that combines advantage clipping to prevent destructive policy updates with a warm-up phase that allows the critic to mature before influencing the actor, and (3) a scalable generalized critic weighting scheme that extends traditional reward-weighted methods while preserving model diversity through Wasserstein regularization. Through extensive experiments on Stable Diffusion 3, we demonstrate that AC-Flow achieves state-of-the-art performance in text-to-image alignment tasks and generalization to unseen human preference models. Our results demonstrate that even with a computationally efficient critic model, we can robustly finetune flow models without compromising generative quality, diversity, or stability.
J. Fan*, C. Cheng, S. Shen, X. Zhou, G. Liu · Under Review
AC-Flow: actor-critic with intermediate feedback for flow matching — reward shaping + dual-stability + Wasserstein regularization. Robust fine-tuning on SD3 without collapse.
Actor-critic with step-level reward · Stable SD3 fine-tuning without collapse
We introduce PRANCE, a Vision Transformer compression framework that jointly optimizes the activated channels and reduces tokens, based on the characteristics of inputs. Specifically, PRANCE leverages adaptive token optimization strategies for a certain computational budget, aiming to accelerate ViTs' inference from a unified data and architectural perspective. However, the joint framework poses challenges to both architectural and decision-making aspects. Firstly, while ViTs inherently support variable-token inference, they do not facilitate dynamic computations for variable channels. To overcome this limitation, we propose a meta-network using weight-sharing techniques to support arbitrary channels of the Multi-head Self-Attention and Multi-layer Perceptron layers, serving as a foundational model for architectural decision-making. Second, simultaneously optimizing the structure of the meta-network and input data constitutes a combinatorial optimization problem with an extremely large decision space, reaching up to around 1014, making supervised learning infeasible. To this end, we design a lightweight selector employing Proximal Policy Optimization for efficient decision-making. Furthermore, we introduce a novel "Result-to-Go" training mechanism that models ViTs' inference process as a Markov decision process, significantly reducing action space and mitigating delayed-reward issues during training. Extensive experiments demonstrate the effectiveness of PRANCE in reducing FLOPs by approximately 50%, retaining only about 10% of tokens while achieving lossless Top-1 accuracy. Additionally, our framework is shown to be compatible with various token optimization techniques such as pruning, merging, and sequential pruning-merging strategies. The code is available at https://github.com/ChildTang/PRANCE.
Y. Li, C. Tang, Y. Meng, J. Fan, Z. Chai, X. Ma, Z. Wang, W. Zhu · IEEE TPAMI
The exploration problem is one of the main challenges in deep reinforcement learning (RL). Recent promising works tried to handle the problem with population-based methods, which collect samples with diverse behaviors derived from a population of different exploratory policies. Adaptive policy selection has been adopted for behavior control. However, the behavior selection space is largely limited by the predefined policy population, which further limits behavior diversity. In this paper, we propose a general framework called Learnable Behavioral Control (LBC) to address the limitation, which a) enables a significantly enlarged behavior selection space via formulating a hybrid behavior mapping from all policies; b) constructs a unified learnable process for behavior selection. We introduce LBC into distributed off-policy actor-critic methods and achieve behavior control via optimizing the selection of the behavior mappings with bandit-based meta-controllers. Our agents have achieved 10077.52% mean human normalized score and surpassed 24 human world records within 1B training frames in the Arcade Learning Environment, which demonstrates our significant state-of-the-art (SOTA) performance without degrading the sample efficiency.
J. Fan*, Y. Zhuang, Y. Liu, J. Hao, B. Wang, J. Zhu, H. Wang, S.-T. Xia
LBC: learnable hybrid behavior mapping + bandit meta-controller. Unified framework for exploration control in deep RL.
Ranked 5/4176 · 10,077% mean human score · 24 world records · 78× data efficiency
To obtain higher sample efficiency and superior final performance simultaneously has been one of the major challenges for deep reinforcement learning (DRL). Previous work could handle one of these challenges but typically failed to address them concurrently. In this paper, we try to tackle these two challenges simultaneously. To achieve this, we firstly decouple these challenges into two classic RL problems: data richness and exploration-exploitation trade-off. Then, we cast these two problems into the training data distribution optimization problem, namely to obtain desired training data within limited interactions, and address them concurrently via i) explicit modeling and control of the capacity and diversity of behavior policy and ii) more fine-grained and adaptive control of selective/sampling distribution of the behavior policy using a monotonic data distribution optimization. Finally, we integrate this process into Generalized Policy Iteration (GPI) and obtain a more general framework called Generalized Data Distribution Iteration (GDI). We use the GDI framework to introduce operator-based versions of well-known RL methods from DQN to Agent57. Theoretical guarantee of the superiority of GDI compared with GPI is concluded. We also demonstrate our state-of-the-art (SOTA) performance on Arcade Learning Environment (ALE), wherein our algorithm has achieved 9620.33% mean human normalized score (HNS), 1146.39% median HNS and surpassed 22 human world records using only 200M training frames. Our performance is comparable to Agent57's while we consume 500 times less data. We argue that there is still a long way to go before obtaining real superhuman agents in ALE.
J. Fan*, C. Xiao
GDI: optimizing the data distribution is the key to superhuman RL efficiency. Unified framework for diverse RL algorithms.
Agent57 beaten with 500× less data & 2× avg performance
Hover a node to highlight connections. Colours mark the research theme; arrows show how ideas evolved.
Research North Star
My long-term goal is AI that improves itself with minimal human supervision. Everything I build ladders into three autonomous capabilities:
Auto Self-Evolution
Models that improve themselves
Generative models and reasoning LLMs that self-improve from their own outputs and environment feedback — no human-labeled data. Reward-weighted, collapse-free, process-supervised online RL.
ORW-CFM-W2ADRPOAC-FlowCESAR
Auto Exploration
Agents that explore on their own
Sample-efficient, self-directed exploration that enlarges what an agent can discover — learnable behavior control and data-distribution optimization that reached superhuman play with orders of magnitude less data.
LBCGDI
Auto Research
AI that does research
The horizon: agents that run the full scientific loop — hypothesize, experiment, analyze, refine — autonomously. Agentic RL that turns self-evolution and self-exploration into self-driven discovery.
Agentic RLOngoing
Research Interests
RL Post-Training for Generative Models
Collapse-free online RLHF for flow/diffusion models. No human-collected preference data needed — models improve from their own generations (ORW-CFM-W2, ADRPO, AC-Flow).
Multimodal Reasoning LLMs
Process-reward RL for audio/visual LLMs — fixing test-time inverse scaling so reasoning actually helps, not hurts (CESAR).
Superhuman Deep RL
Sample-efficient RL that exceeds human performance. Broke 24 Atari world records with 78× less data (LBC), and beat Agent57 with 500× less data (GDI).
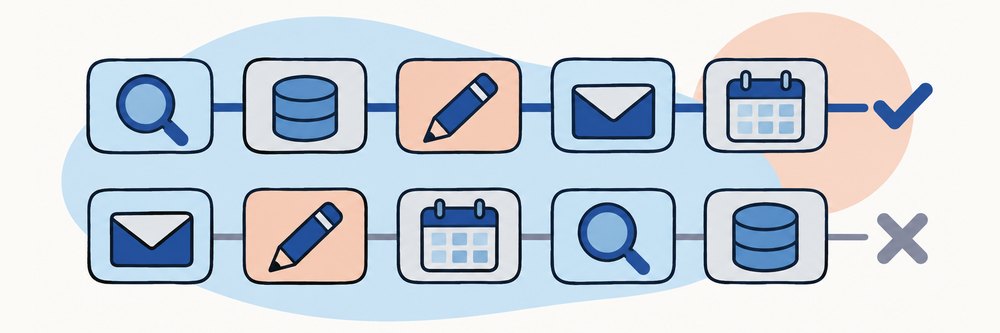
Agentic RL
RL for tool-using, multi-turn agents — rewarding the order of tool calls and the state they leave behind, and training voice agents end to end in native speech (Procedure-Aware RL, SpeechGym).
Recursive Self-Improvement
Models that keep improving themselves: each improved policy becomes the critic and teacher of its successor, removing human scaffolding from RL post-training step by step.
Agentic Scientific Discovery
Agents that run a design loop on their own — propose, test, learn — starting with protein design that keeps improving from its own designs (ProteinZero), toward agents that run the research loop itself.
Today's AI is frozen after training. I work to change that: AI that never stops getting better, with progressively less human scaffolding.
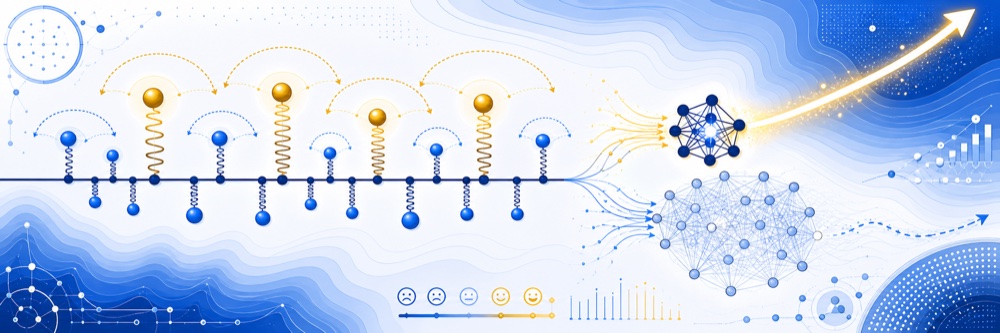
How to read it. Each step adds something the model can do on its own: improve from its own samples without collapsing (ORW-CFM-W2, ADRPO), reason step by step with the process rewarded (CESAR), act in speech and with tools (SpeechGym, Procedure-Aware RL) — and next, run the research loop itself, as an AI scientist.
Awards & Academic Service
Selected Awards
National Scholarship ×2, Top 1% — Nankai Univ.
Ranked 1st / 83 in major — Nankai Univ.
Outstanding Graduates (Top 1%) — Nankai Univ.
Tang Lixin Scholarship (Top 1%)
GPA 4.0/4.0 — UIUC Ph.D.
ICLR 2023 Oral (notable top 5%; ranked 5/4176) — LBC paper
GPA 3.97/4.0, Top 1.3% — Tsinghua M.Eng.
Reviewer
ICML 2023–2024 · 2025 · 2026
ICLR 2024 · 2025 · 2026
NeurIPS 2022–2023 · 2024–2026
COLM 2026 · CVPR 2026 · WACV 2027
AAAI 2025 · 2027 · AISTATS 2025 · KDD 2024
Conference Deadlines
Key AI/ML venue deadlines I track — for the full list see ccfddl.com.
Contact
Happy to discuss research, internships, or collaborations. Best reached by email. jiajunf3@illinois.edu · Siebel Center for CS, UIUC · CV · LinkedIn · ORCID

 RL Post-Training for Generative Models
 Multimodal Reasoning LLMs
 Superhuman Deep RL
 Agentic RL
 Recursive Self-Improvement
 Agentic Scientific Discovery
 Email
 OpenReview
 GitHub
 LinkedIn
 News
 Featured
 Publications
 North Star
 Research
 Impact
 Vision
 Awards
 Deadlines
 Blog
 CV
 Contact


 Research Paper Network
 Projects