


A banana on the left of an apple
SD3
ORW-CFM-W2
At a glance
Can a flow-matching image model learn from a reward alone, online, from its own samples, without collapsing? Yes: weight its own samples by their reward, and hold it near the base model with a Wasserstein‑2 bound it can compute.
Trained on its own samples, it reaches the best reward. A fixed dataset stops short.
Finding 02Without it, the model ends up drawing one picture. With it, the samples stay varied.
Finding 03Raising α keeps it closer to the base model, trading reward for diversity.
Finding 04The highest CLIP score of all methods compared, with diversity close to the base model.
The problem
Methods such as DDPO need each sample's likelihood. For a continuous flow, that means integrating the model's divergence along its whole path.
Re-weighting data collected in advance cannot reach the best policy: the online–offline gap. DPO also needs pairs and filtered data.
A model that keeps training on its own best samples narrows until it makes one image: the over-optimization seen in diffusion models.
What is missing: an online method with a limit that a flow model can actually compute.
The idea Lemma 1
We prove that re-weighting its own samples round after round sharpens the model toward the highest reward, until it makes the same image every time. The usual limit, a KL penalty, needs the very likelihood a flow cannot afford.
Schematic of the paper's analysis (Theorem 2, Lemma 1 and Theorem 5), not measured. Bars: share of samples in each of five modes; dashed: the base model.
So keep the online loop, and add a limit the model can compute.
How it works
Each round it weights its own samples by their reward and trains on them. A Wasserstein‑2 bound, computed from the two models' vector fields, keeps it near the base model.
w(x1) · ‖vθ(t, x) − ut(x | x1)‖2
Trains on its own samples, each weighted by its reward. Online, the weights compound round after round.
W22 ≤ e2L ∫01 E ‖vft − vref‖2 ds
Bounds how far it drifts from the base model with only the two vector fields, no likelihood. It enters the loss with weight α.
τ sets how fast it converges; α sets where it settles.
The evidence Finding 01
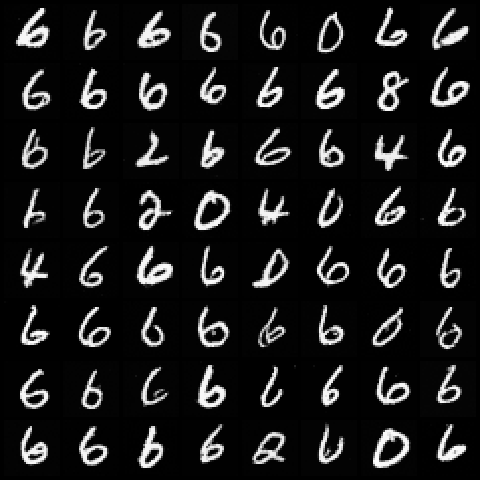
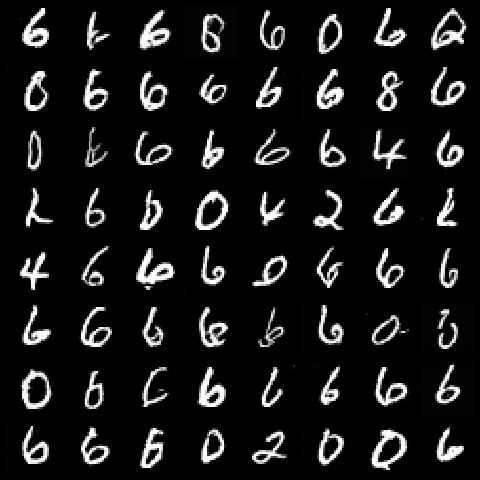
Rewarded for even digits, a model trained on its own samples reaches the best possible reward. Re-weighting a fixed dataset stops short.
Fine-tuning an MNIST flow model toward even digits reward = p(even) − p(odd), no W2 term (α = 0)
Online, τ = 10Online, τ = 0.01Offline, RW-CFMNo reward weight, τ = 0Optimal
What each run generates
The paper's own samples, one grid per run. The larger τ, the greedier it gets.
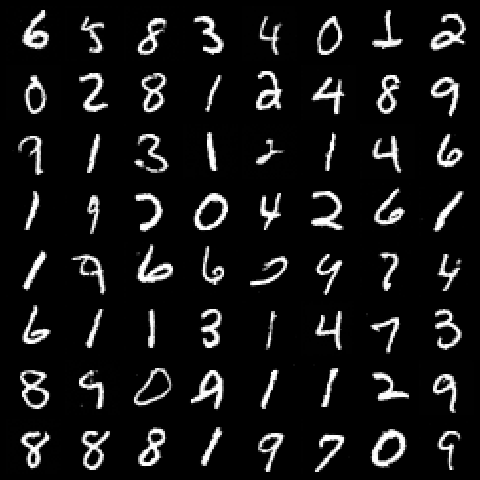
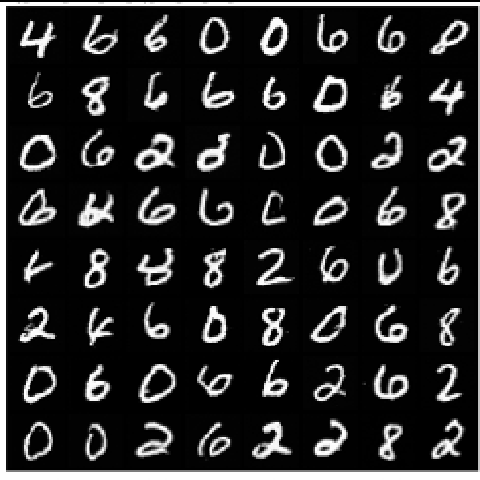
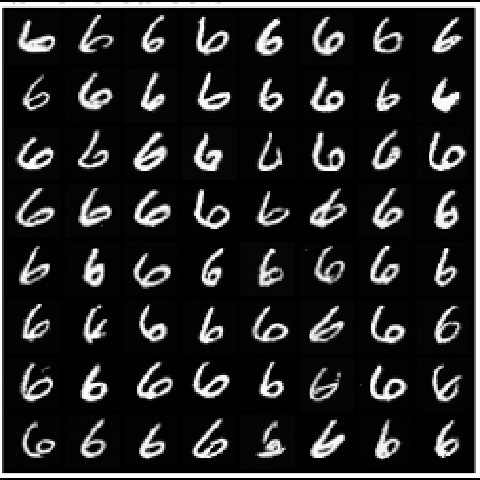
Paper, Fig. 2. Curves traced from the paper's figure, without its shaded spread.
Learning from what it just generated takes it where no fixed dataset reaches.
The evidence Finding 02
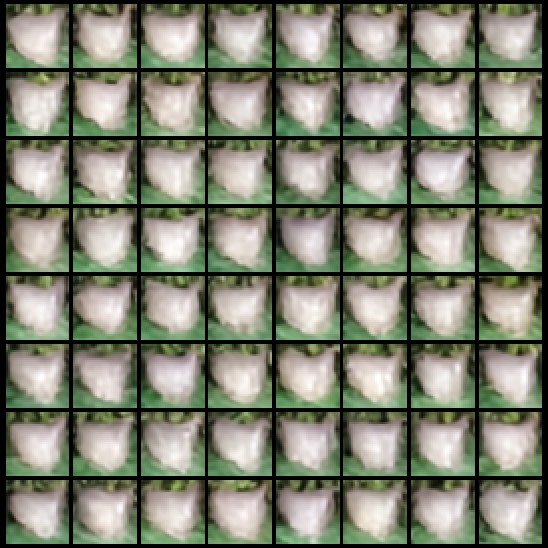
Rewarded for cats, dogs or birds, the model without the bound draws the same picture over and over. With it, the samples stay varied at a similar reward.
“an image of cat”
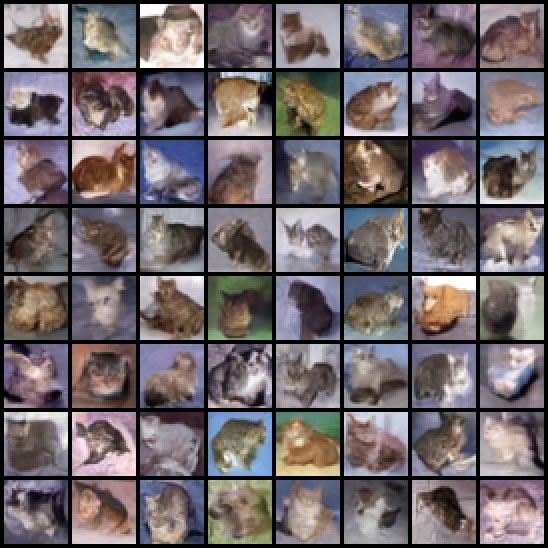
“an image of dog”
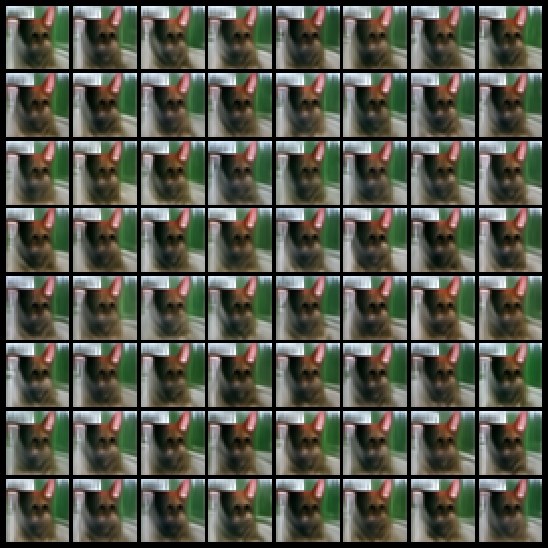
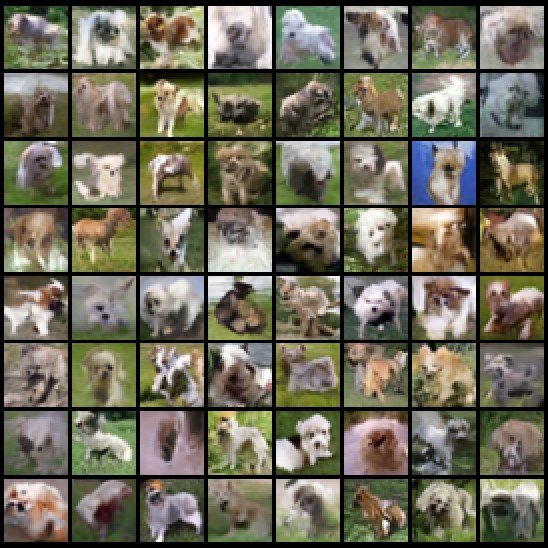
“an image of bird”
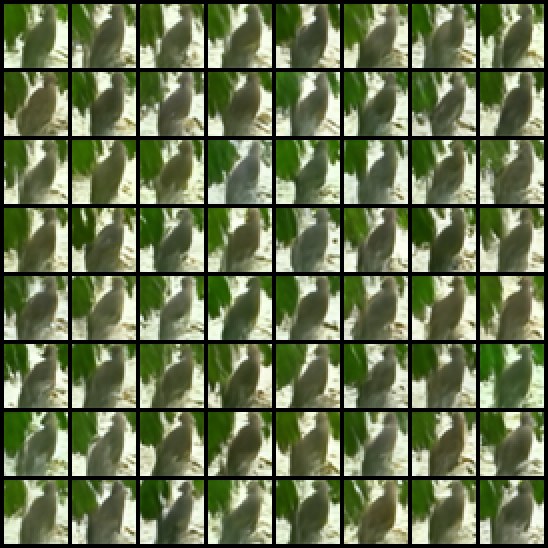
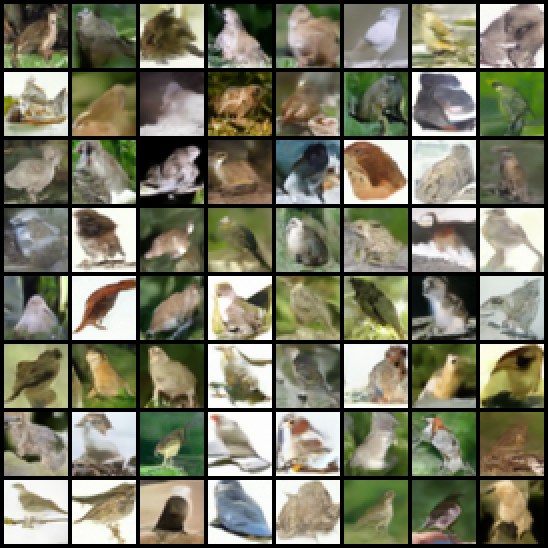
The cat run, step by step W2 distance estimated by its upper bound
Paper, Figs. 11, 13 and 14: an unconditional CIFAR-10 flow model with a CLIP reward, τ = 1. Curves traced from Fig. 11; dashed: the pre-trained model.
Without a limit, it drifts ever further from where it started; with the bound, it stays close.
The evidence Finding 03
Raise α and the model stays closer to the base model, giving up some reward in exchange. Each point on the curves is fine‑tuned separately, at its own α.
Making CIFAR-10 images easy to compress reward from the JPEG file size, τ = 1
Image compression, CIFAR-10 τ = 1
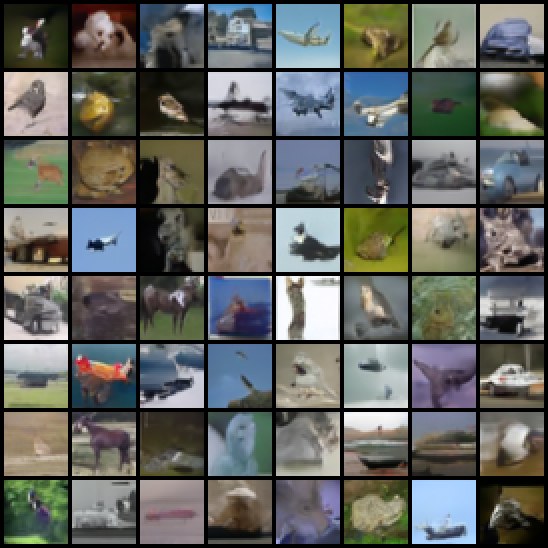
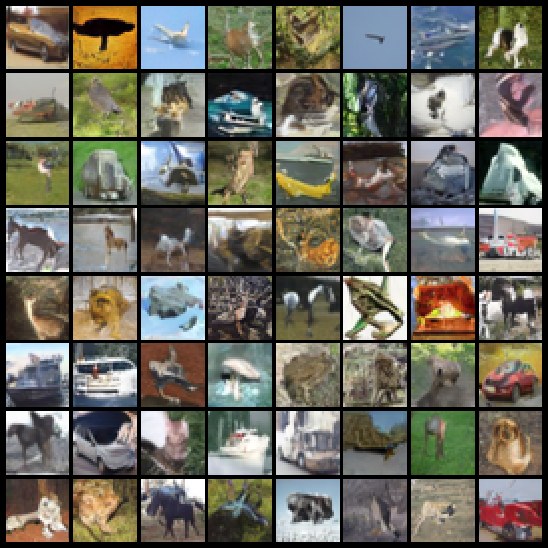
Even digits, MNIST τ = 10
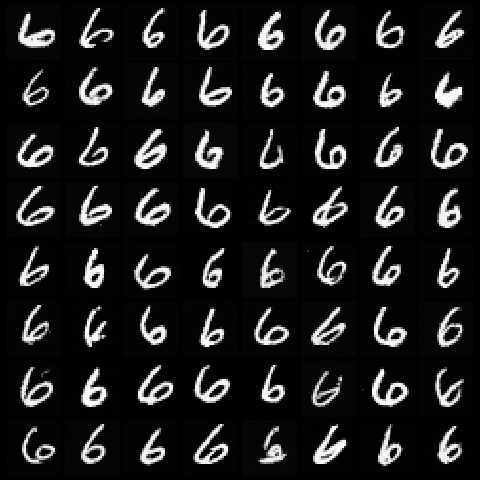
Paper, Figs. 3 and 4. Curves traced from Fig. 4e and 4f; dashed: the pre-trained model.
The trade-off is set with one number, not with a new dataset.
The evidence Finding 04
Fine-tuned on “a cat in the sky” with a CLIP reward, it scores highest of all methods compared, with diversity close to the base model. The W2 bound lifts every method it is added to.
Prompt: “a cat in the sky”
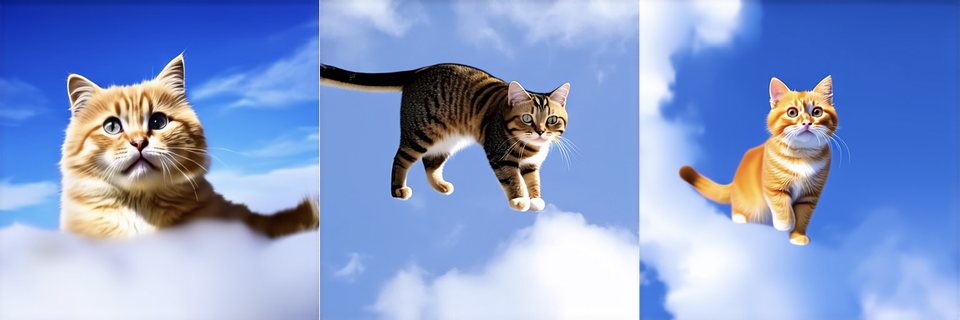
Paper, Table 1 and Fig. 8. Scores averaged across 64 samples; diversity is the mean pairwise distance between CLIP embeddings. Three samples per method, as shown in the paper.
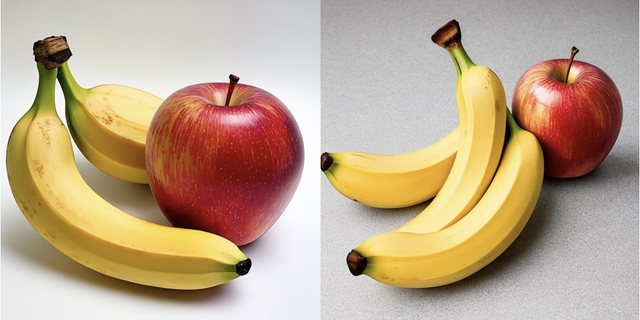
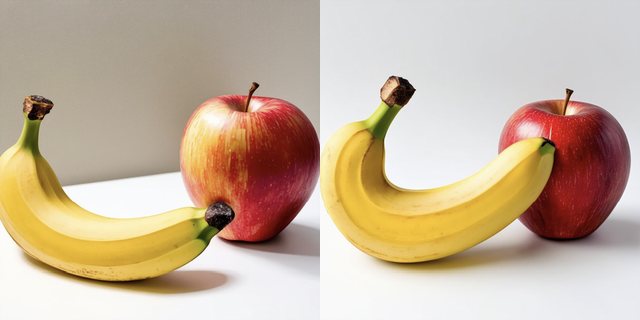
A banana on the left of an apple
SD3
ORW-CFM-W2
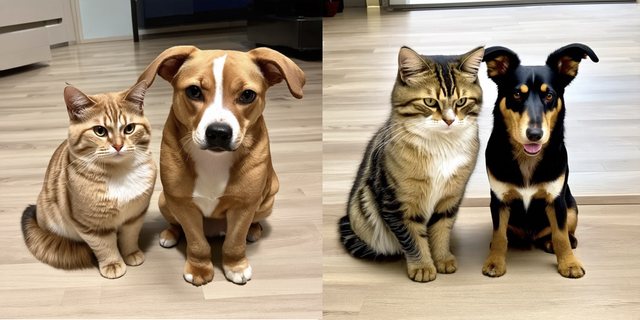
A cat on the left of a dog.
SD3
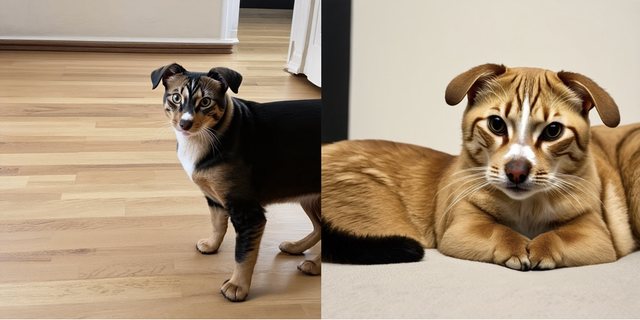
ORW-CFM-W2
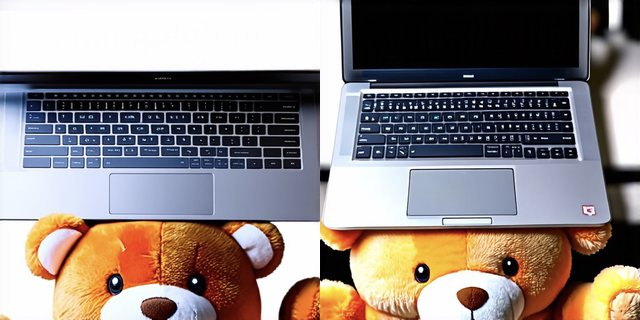
A laptop on top of a teddy bear
SD3
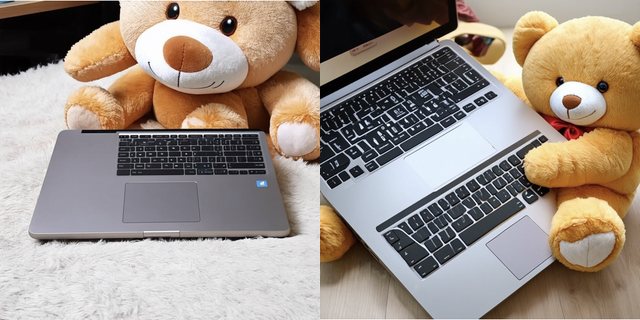
ORW-CFM-W2
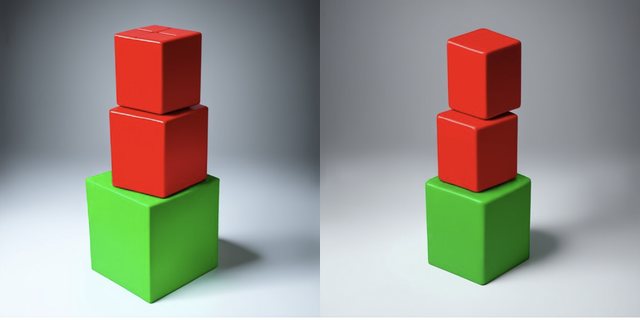
A stack of 3 cubes. A red cube is on the top, sitting on a red cube. The red cube is in the middle, sitting on a green cube. The green cube is on the bottom.
SD3
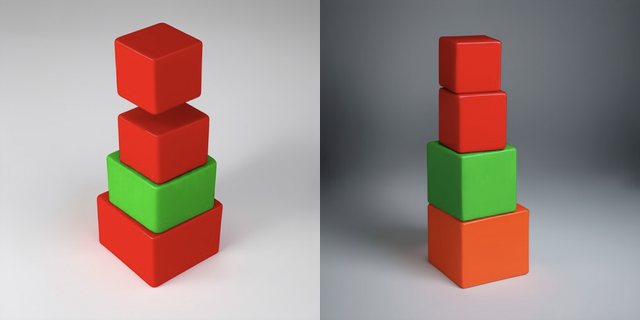
ORW-CFM-W2
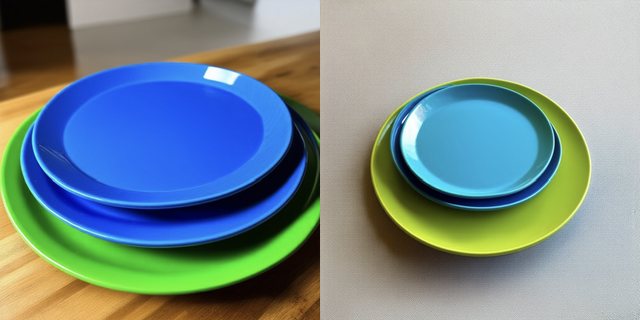
A stack of 3 plates. A blue plate is on the top, sitting on a blue plate. The blue plate is in the middle, sitting on a green plate. The green plate is on the bottom.
SD3
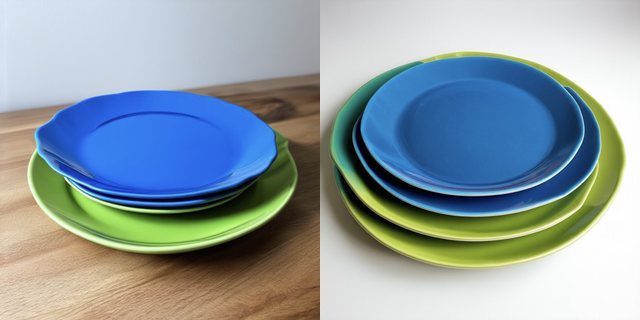
ORW-CFM-W2
An emoji of a baby panda wearing a red hat, green gloves, red shirt, and green pants
SD3
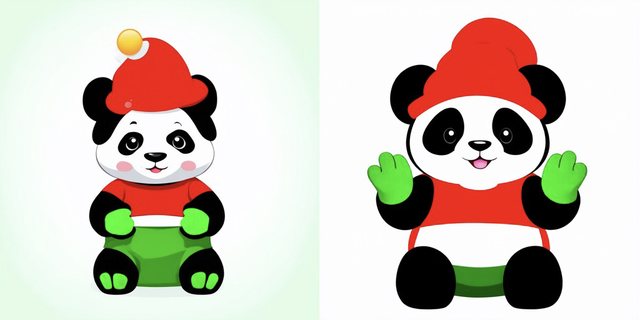
ORW-CFM-W2
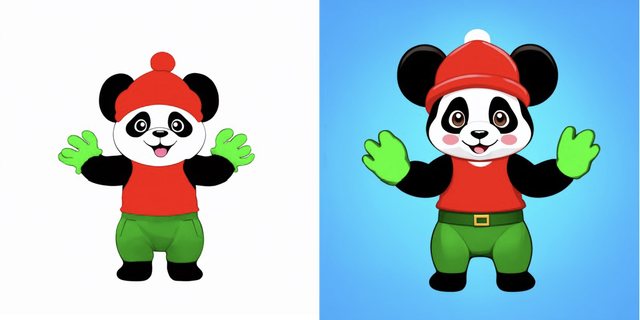
Paper, Figs. 7 and 10; prompts from DrawBench as used in DPOK, with the paper's own wording. Fig. 7 samples every method with the same random seeds.
Better placement and attributes, without giving up image quality.
Why it matters Finding 05
It needs only a score for each image it makes: no human‑collected data, no filtered datasets, no gradient of the reward.
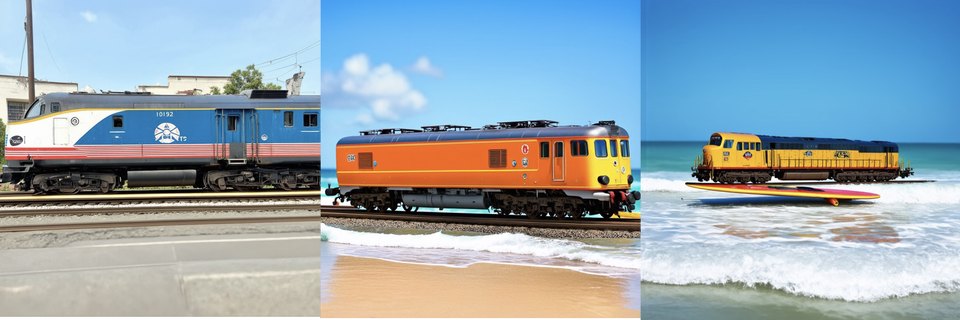
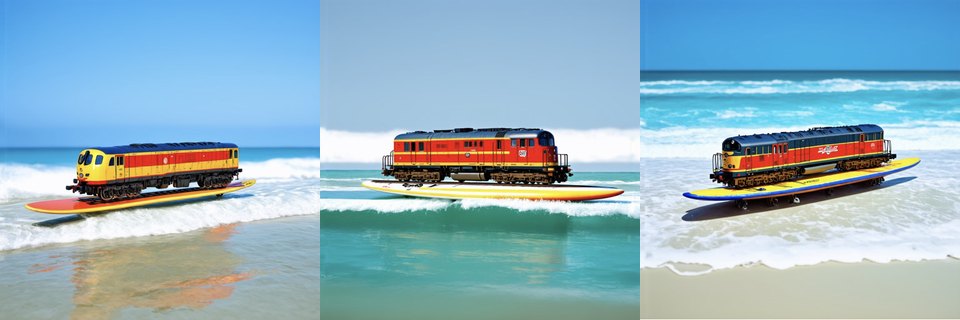
Stable Diffusion 3, “a train on top of a surfboard”, with three other reward models
HPS-V2
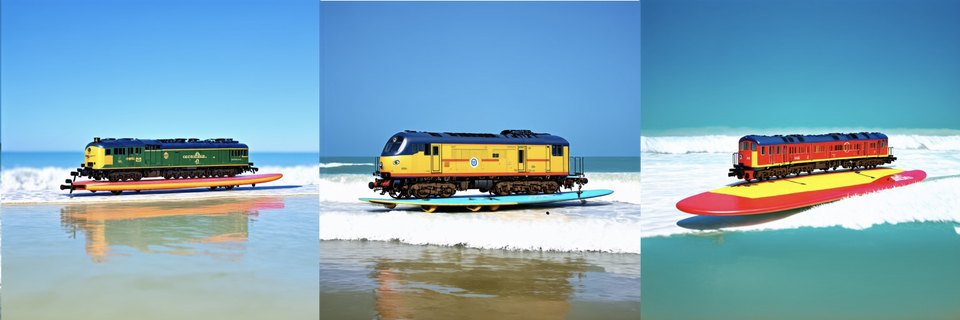
Pick Score
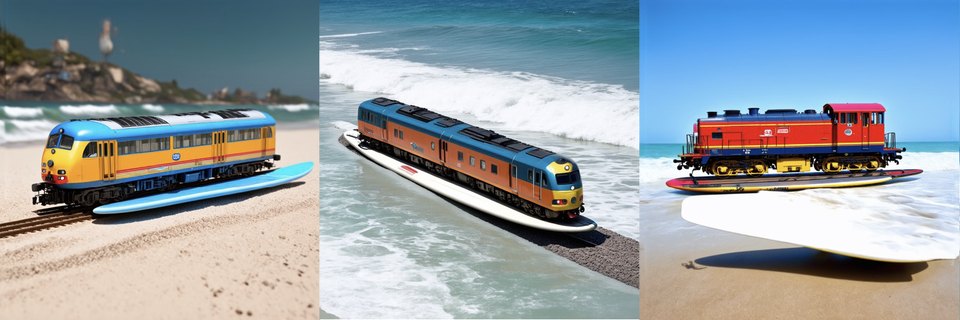
Alpha Clip
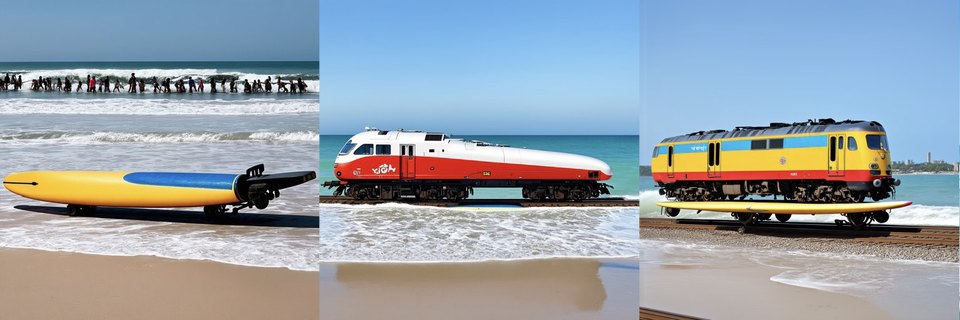
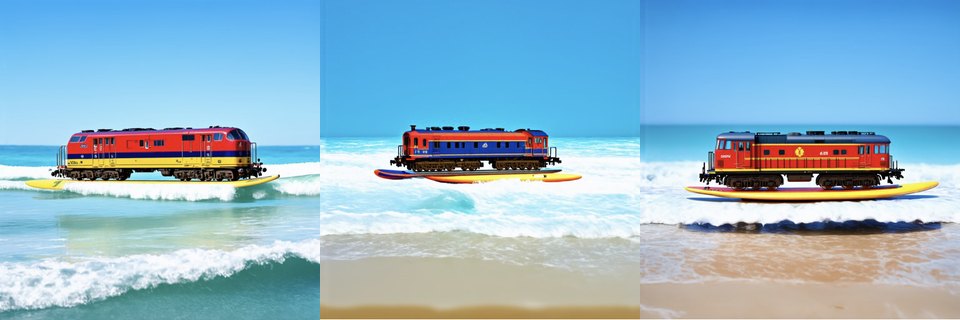
Paper, Fig. 9, in the paper’s order.
A classifier, a JPEG file size, CLIP, HPS‑V2, Pick Score, Alpha Clip: one method, no reward‑specific changes.
Every training image is one it generated itself. Flip the sign of the reward and the same model learns odd digits instead of even ones.
τ sets how fast it converges and α where it settles, so fine-tuning stays under control.
The film
Opens the film page.
Cite
International Conference on Learning Representations 2025 (ICLR 2025).
@inproceedings{fan2025online,
  title={Online Reward-Weighted Fine-Tuning of Flow Matching
  with Wasserstein Regularization},
  author={Jiajun Fan and Shuaike Shen and Chaoran Cheng
  and Yuxin Chen and Chumeng Liang and Ge Liu},
  booktitle={The Thirteenth International Conference on
  Learning Representations},
  year={2025},
  url={https://openreview.net/forum?id=2IoFFexvuw}
}