

Score only the finished image
what most fine-tuning methods do
Every step gets the same credit, so an early mistake goes uncorrected and a good step goes unrewarded.
At a glance
Can an image model learn from feedback on every step of its generation, not only on the finished picture? AC-Flow trains a small critic that scores each intermediate step of Stable Diffusion 3, and keeps it stable while the model learns online.
Plain actor-critic never settles. Three safeguards bring both losses down and keep them there.
Finding 02Without the safeguards, the reward peaks early and its images turn into the same close-up.
Finding 03Trained only on CLIP score, it also scores highest on HPS v2 and ImageReward.
Finding 04Where each object goes, which color goes where, and what the sign says.
The problem
A flow model draws an image in many small steps, yet most fine-tuning methods score only the last one. A critic could score every step, but trained naively online, it breaks.
what most fine-tuning methods do
Every step gets the same credit, so an early mistake goes uncorrected and a good step goes unrewarded.
value regression, trained online on its own samples
The critic and the model feed each other’s errors: the loss runs away and the images collapse.
What is missing: credit for each step, from a critic that stays stable.
The idea Step-level credit
Reward-weighted fine-tuning scales a flow-matching update by how good the final image was. AC-Flow replaces that one number with a weight for every step, set by the reward minus what the critic expected from that step.
Schematic, after the paper’s Fig. 1. Bars: what sets each step’s weight. In AC-Flow, a bar above the line makes a step count for more, below it for less.
Steps that beat the critic’s expectation count for more; steps that fall short count for less.
How it works
The critic is small: a few convolution and MLP layers beside Stable Diffusion 3. Three safeguards make its advice safe to follow online, and a Wasserstein-2 penalty keeps the model close to where it started.
A critic it can trust, and a model kept close to where it started.
The evidence Finding 01
Plain actor-critic training on Stable Diffusion 3 never settles. Each safeguard pulls the actor loss further down; with all three, both losses come down early and stay down.
plain actor-critic+ reward shaping+ advantage clippingAC-Flow, all three
Actor losslog scale
Value losslog scale
The ablation of the paper’s Fig. 2, redrawn from its curves. Shaded: the critic’s warm-up, the first 500 steps.
Reward shaping tames the scale, clipping tames the spikes, and the warm-up lets the critic mature before it steers.
The evidence Finding 02
One prompt, “A dog in the sky”. Without the safeguards the reward peaks early and slides back. AC-Flow keeps climbing.
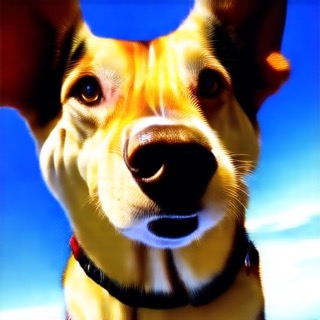
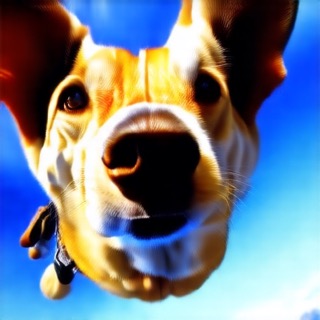
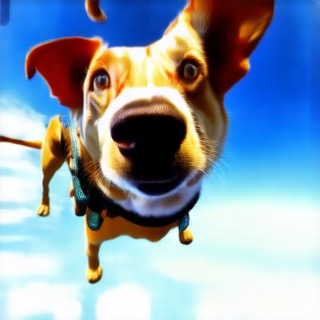
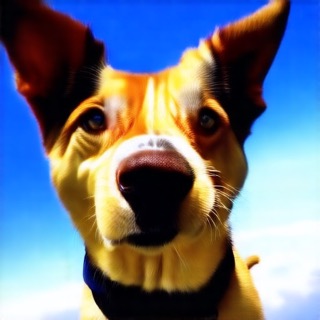
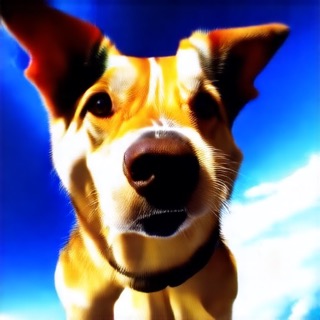
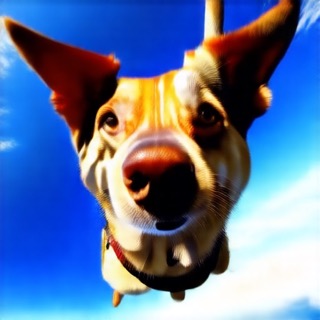
Distorted, and nearly the same close-up every time.
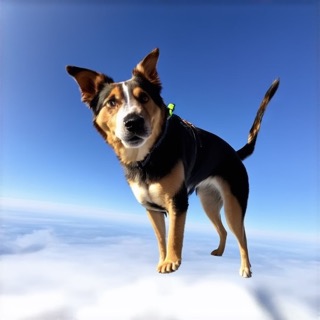
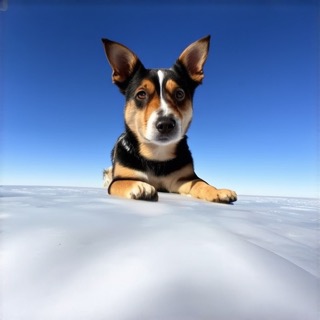
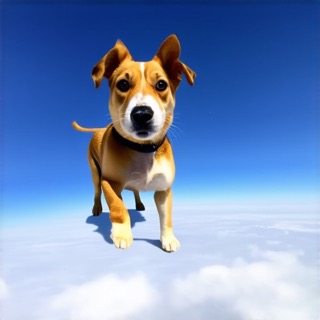
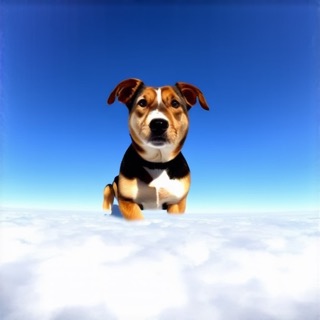
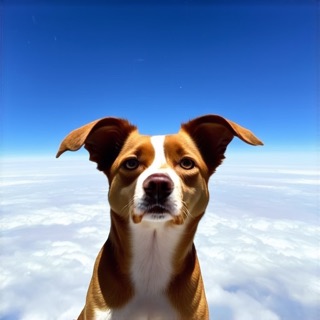
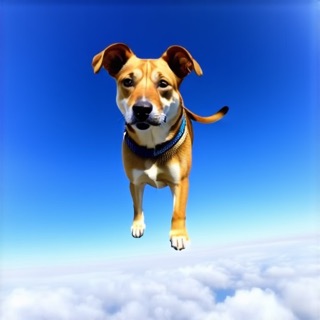
Coherent dogs, in the sky, and varied.
Reward curves from the paper’s Fig. 4, redrawn with its shaded bands; images from its Fig. 2.
With a critic it can trust, more training keeps paying off.
The evidence Finding 03
Every method was fine-tuned on the same reward, CLIP score. AC-Flow scores highest on it, and on two human-preference models that played no part in its training.
DrawBench prompts on Stable Diffusion 3 (SD3, the base model, dashed). Mean and standard error over three seeds, from the paper’s Table 1.
Diversity: the mean distance between CLIP embeddings of images for the same prompt (paper Table 1). The Wasserstein-2 penalty raises alignment and diversity together.
It learns what the prompt asks for, not a trick that pleases one reward model.
The evidence Finding 04
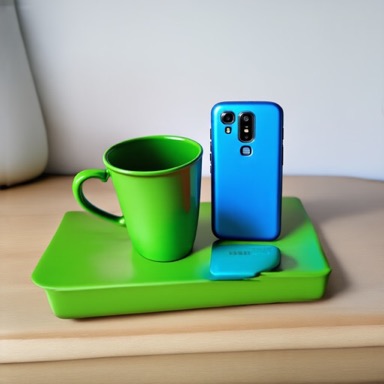
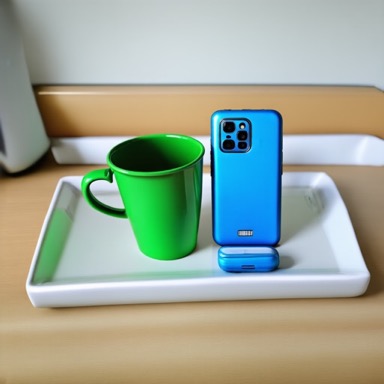
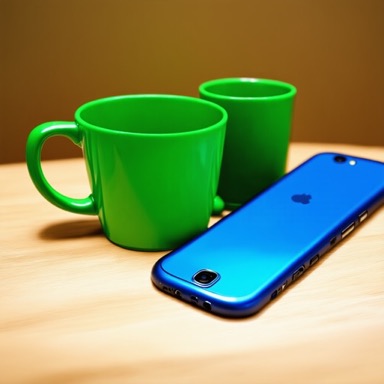
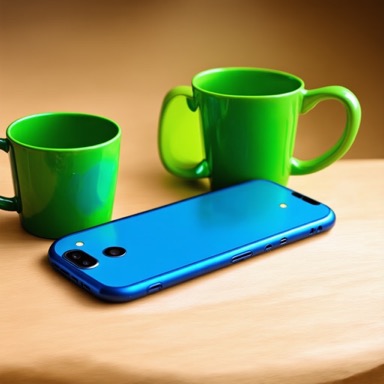
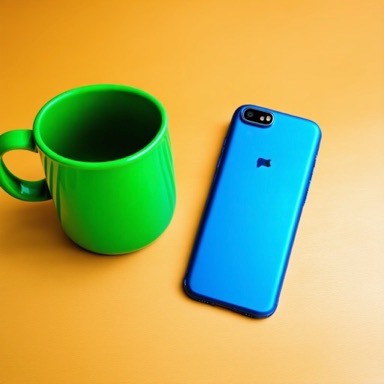
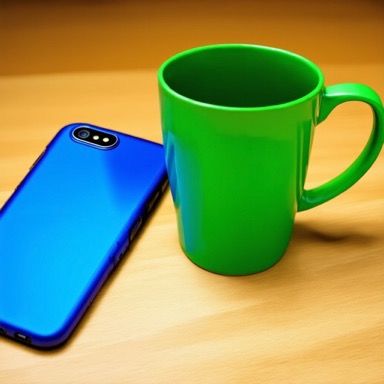
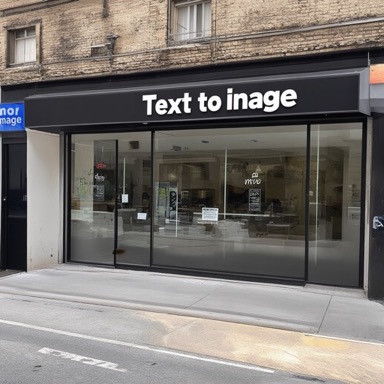
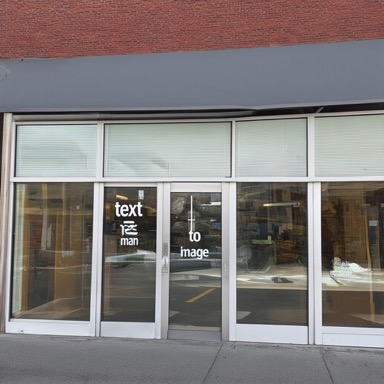
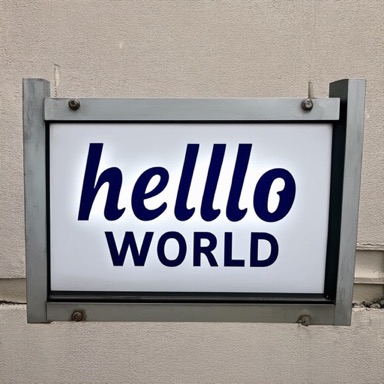
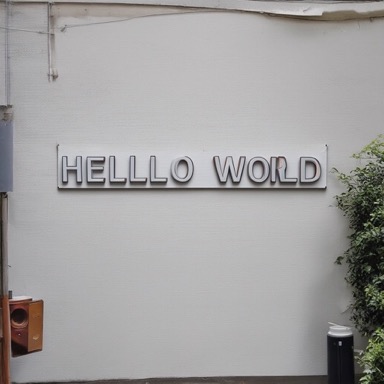
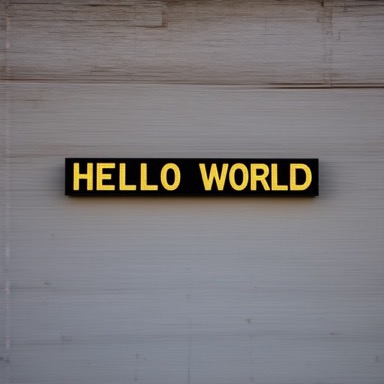
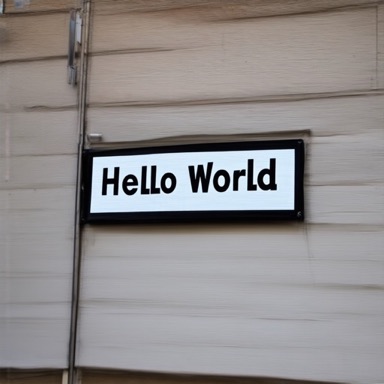
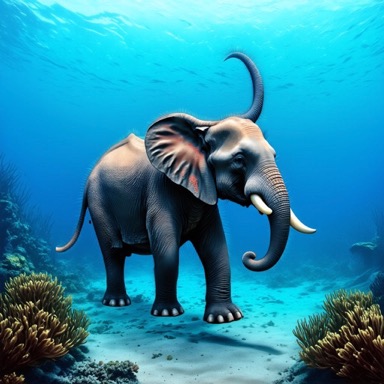
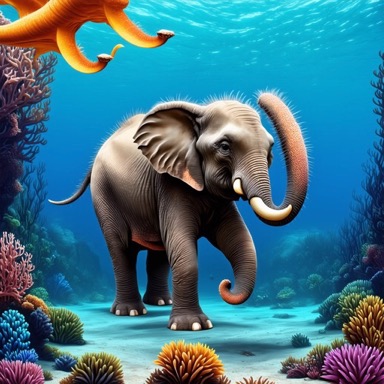
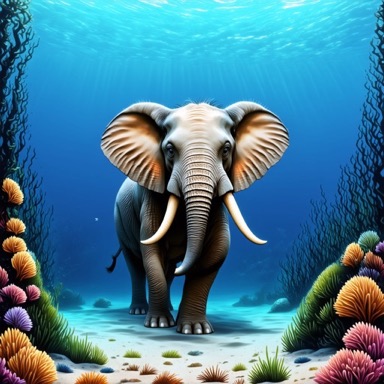
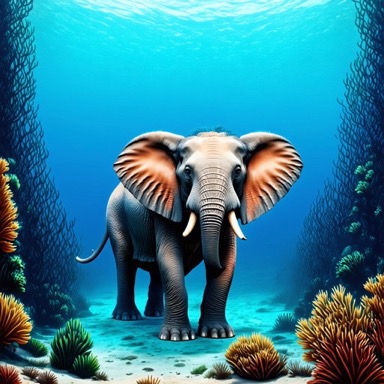
Where each object goes, which color belongs to which object, what the sign says. The same prompts, five methods, two samples each.
Prompt“A banana on the left of an apple.”
Prompt“A black apple and a green backpack.”
Prompt“A green cup and a blue cell phone.”
Prompt“A storefront with ‘Text to Image’ written on it”
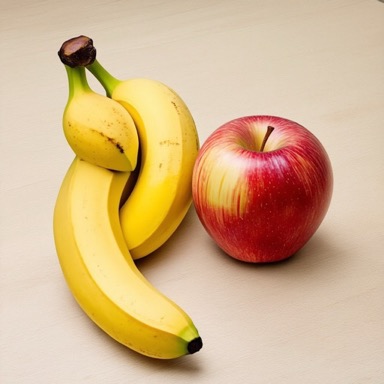
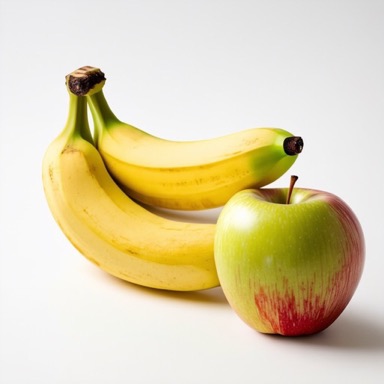
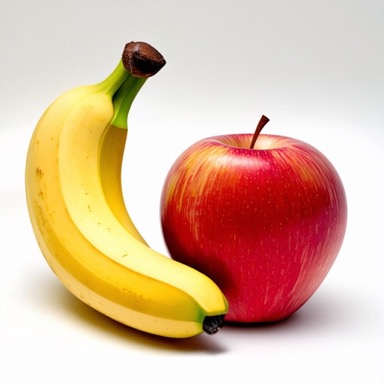
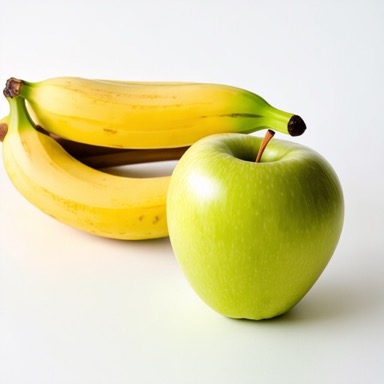
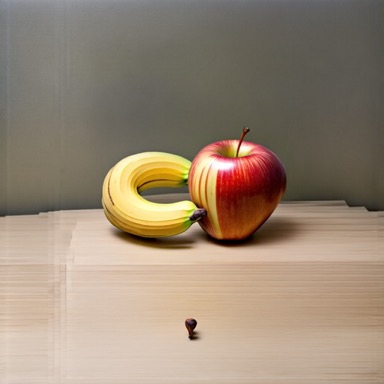
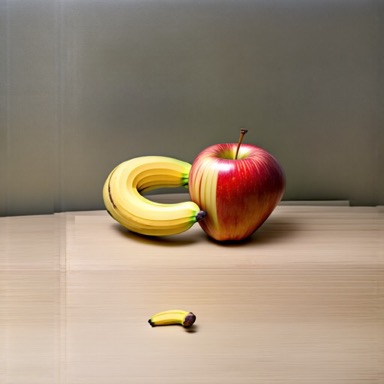
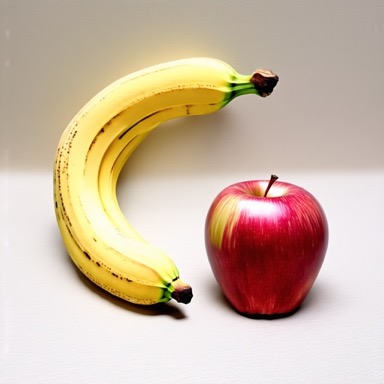
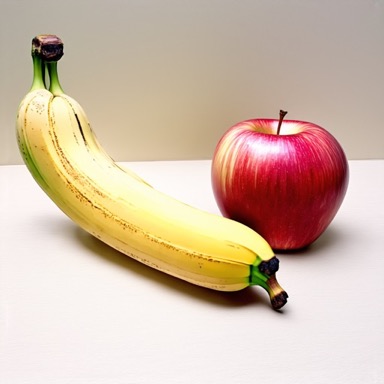
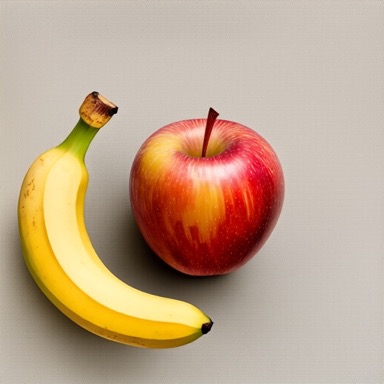
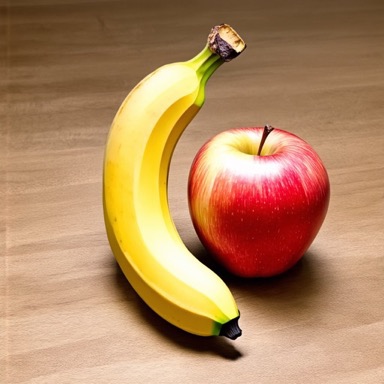
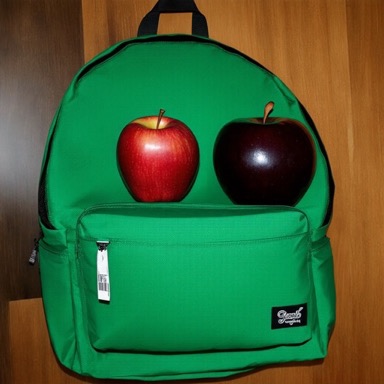
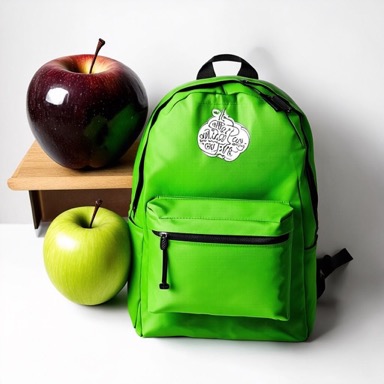
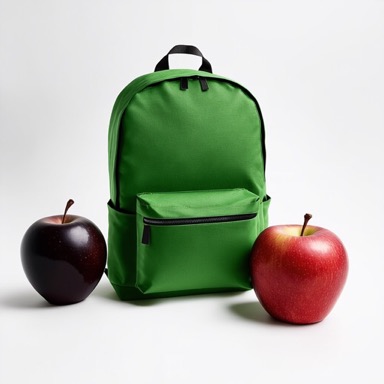
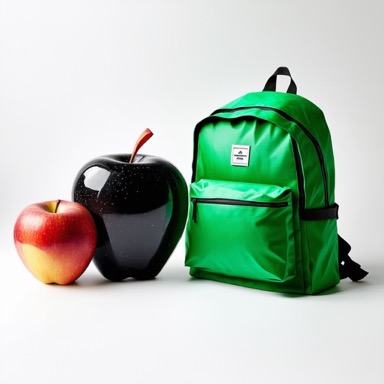
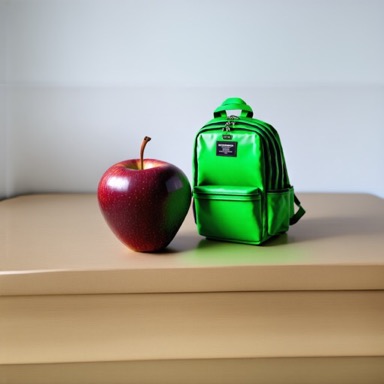
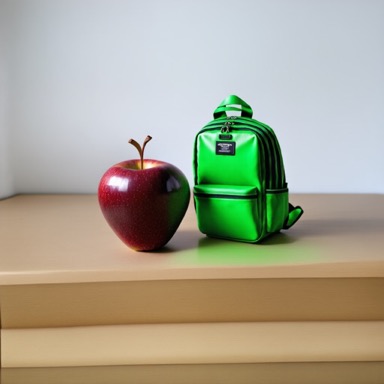
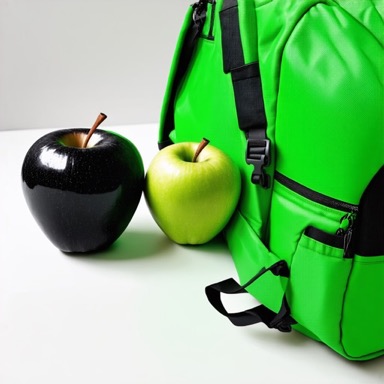
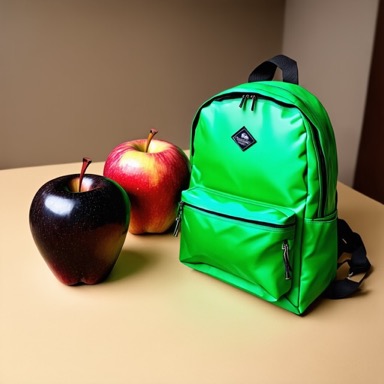
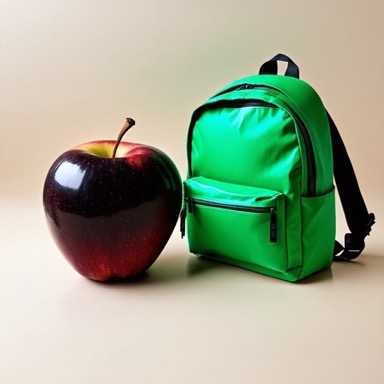
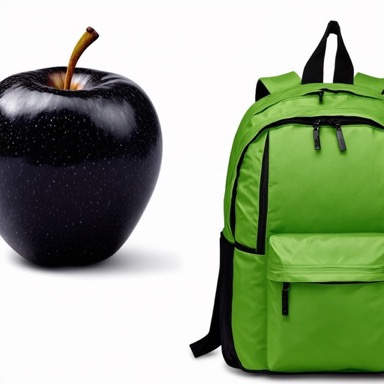
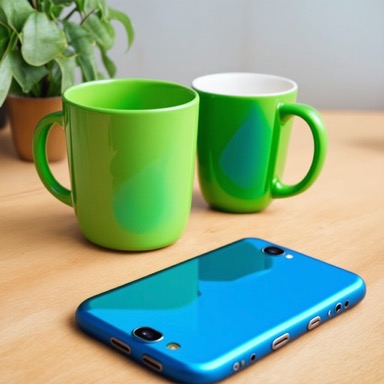
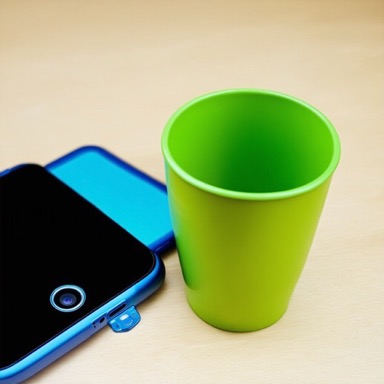
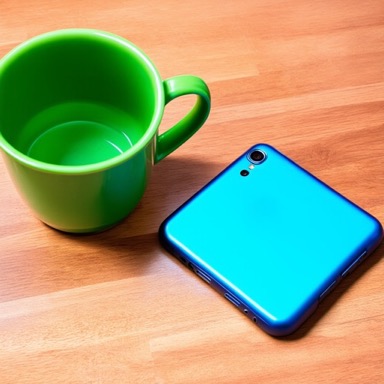
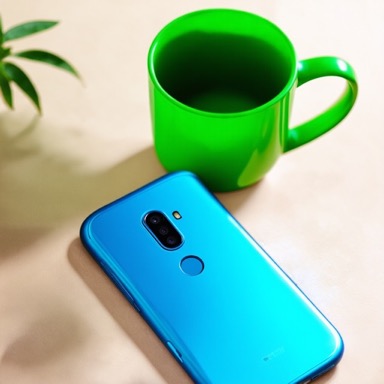
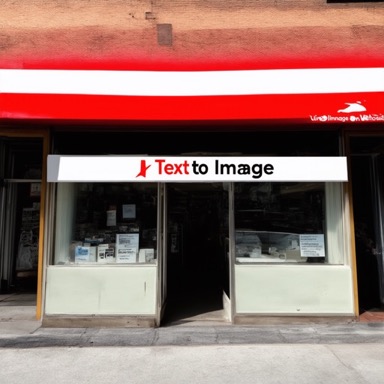
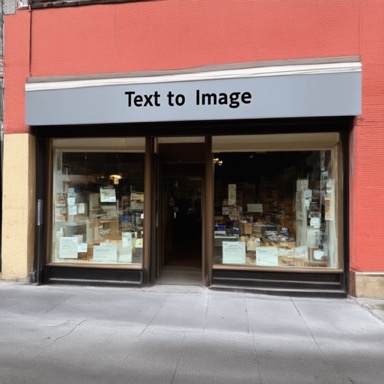
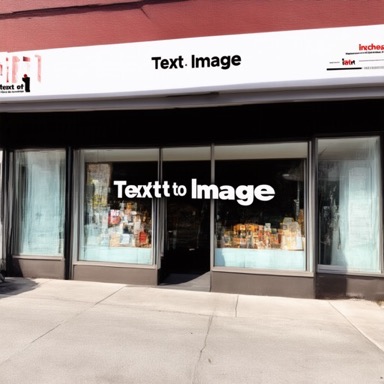
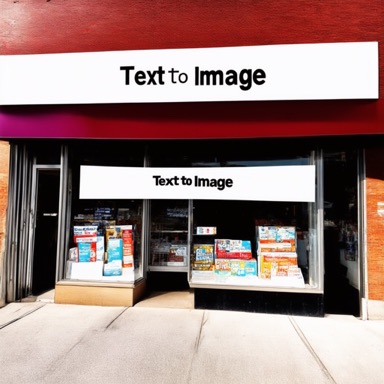
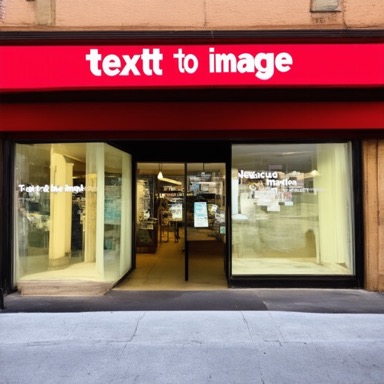
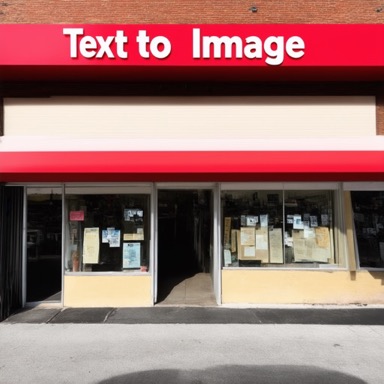
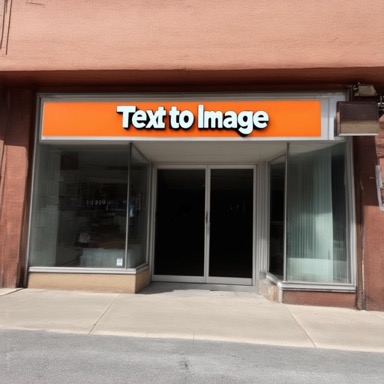
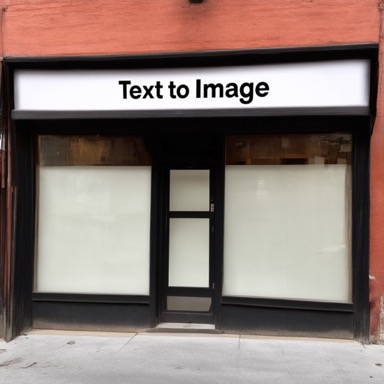
“A sign that says ‘Hello World’.”
“A blue coloured pizza.”
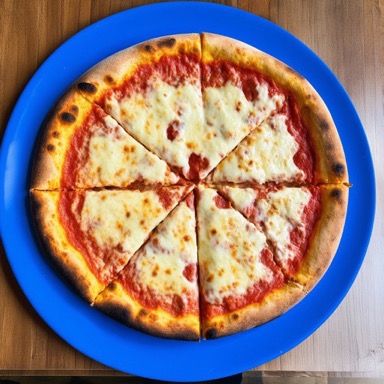
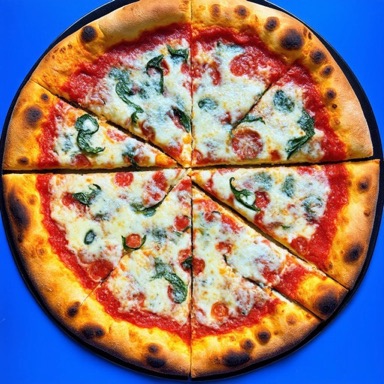
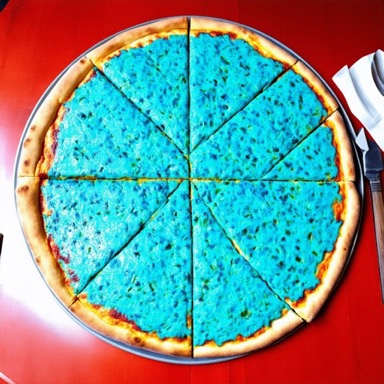
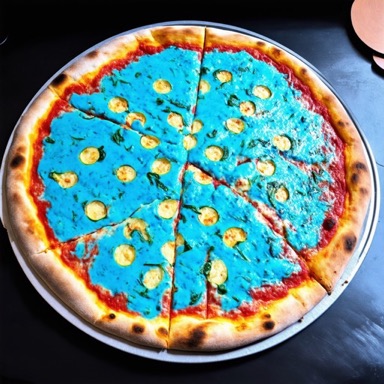
“An elephant under the sea.”
“In late afternoon in January in New England, a man stands in the shadow of a maple tree”
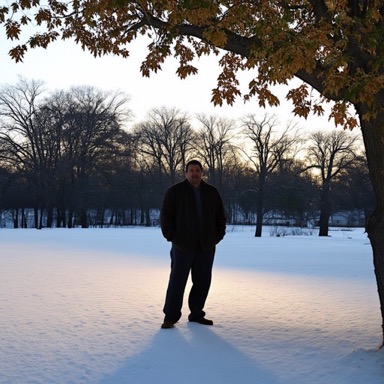
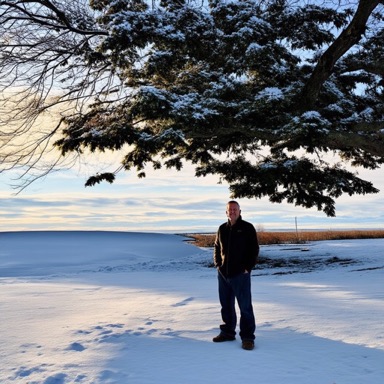
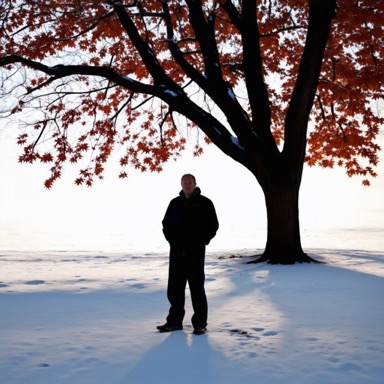
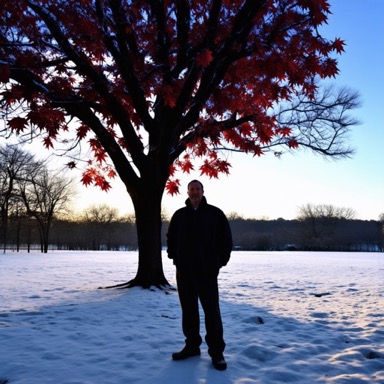
More prompts against the base model, from the paper’s Fig. 5.
Feedback on every step gives finer control over what ends up in the image.
Why it matters Finding 05
The critic adds little. Next to reward-weighted fine-tuning, a run takes about two hours and two gigabytes more, and every run fits on one GPU.
Run timehours per run
Peak GPU memorygigabytes, on one 48 GB GPU
One NVIDIA RTX A6000 per run, from the paper’s Table 2.
A small critic and a light setup let online fine-tuning of Stable Diffusion 3 run on one widely available GPU.
Stable online training on self-generated data points to generators that keep improving through their own outputs.
Swap in another reward, such as one for safety, and the same loop steers the model toward it.
Part of a series on fine-tuning flow models online: ORW-CFM-W2 and ADRPO.
The film
Opens the film page.
Cite
@misc{fan2025finetuningflowmatchinggenerative,
  title={Fine-tuning Flow Matching Generative Models with Intermediate Feedback},
  author={Jiajun Fan and Chaoran Cheng and Shuaike Shen and Xiangxin Zhou and Ge Liu},
  year={2025},
  eprint={2510.18072},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2510.18072}
}