Collect everything
try to visit every unseen situation, as Agent57 and Go-Explore do
Many trials, and much of what they bring back has little value.
- Reaches unseen situations
- Avoids low-value repeats
At a glance
Deep reinforcement learning agents tend to learn fast or end strong, rarely both. What if both come down to one thing: which data the agent learns from? GDI learns which behaviors should collect its data, and sets a new state of the art on Atari with a fraction of the data.
The highest mean human-normalized score on 57 Atari games, ahead of Agent57 and MuZero.
Finding 02Agent57-level play on a five-hundredth of its experience, and 22 human world records.
Finding 03Take away the operator that steers the data, and the same agent falls far behind.
Finding 04A larger space of behavior policies visits more of the game and scores higher.
The problem
Agent57 and Go-Explore try to visit every unseen situation. They ignore which data is worth having, so many of their trials collect data of little value.
try to visit every unseen situation, as Agent57 and Go-Explore do
Many trials, and much of what they bring back has little value.
learn which behaviors collect it, as GDI does
Fewer trials, spent where the data is worth having.
When interactions are limited, which data you collect matters as much as how much.
The idea One lever
Two challenges
Two classic problems
One problem
Two controls
Control which behavior policies collect the data, and you control both.
How it works
Generalized policy iteration updates the agent from its data. GDI adds a second update for which behavior policies collect that data. Switch it off, or shrink the space of behaviors, and familiar algorithms appear.
Seen through GDIseven algorithms, one loop
The same loop with different settingsSchematic of the paper’s operator view. Blue: the RL update of the learner. Green: the update of the data distribution, done by a meta-controller; dashed when an algorithm has none.
The loop stays the same. What changes is whether, and how, the data is chosen.
The evidence Finding 01
Across the 57 games of the Arcade Learning Environment, GDI reaches the highest mean human-normalized score of every agent compared.
Mean human-normalized score (HNS) over 57 Atari games, from the paper’s full comparison table. Green: GDI. Blue: Agent57. Right: frames each agent trained on.
Ending strong no longer requires collecting everything.
The evidence Finding 02
It beats Agent57’s mean score and breaks more human world records, on a five-hundredth of the experience.
Training frames, equivalent human playtime and human world records broken (out of 57 games), from the paper’s comparison tables.
Choosing the data turned decades of play into weeks.
The evidence Finding 03
Fix the behavior policy to a single point, so nothing steers the data, and the same agent falls far behind.
Same space of behaviors, same RL update, same hyperparameters. The only change: no meta-controller, so the behavior policy keeps one fixed index and the data distribution is never optimized.
Normalized by GDI-I³ (dashed line at 1). Bars as drawn in the paper’s ablation figure, which prints no values.
Collecting data is not enough. Choosing it is what works.
The evidence Finding 04
Shrink the behaviors to one temperature knob and the agent scores lower; build them from two separate networks and it scores higher.
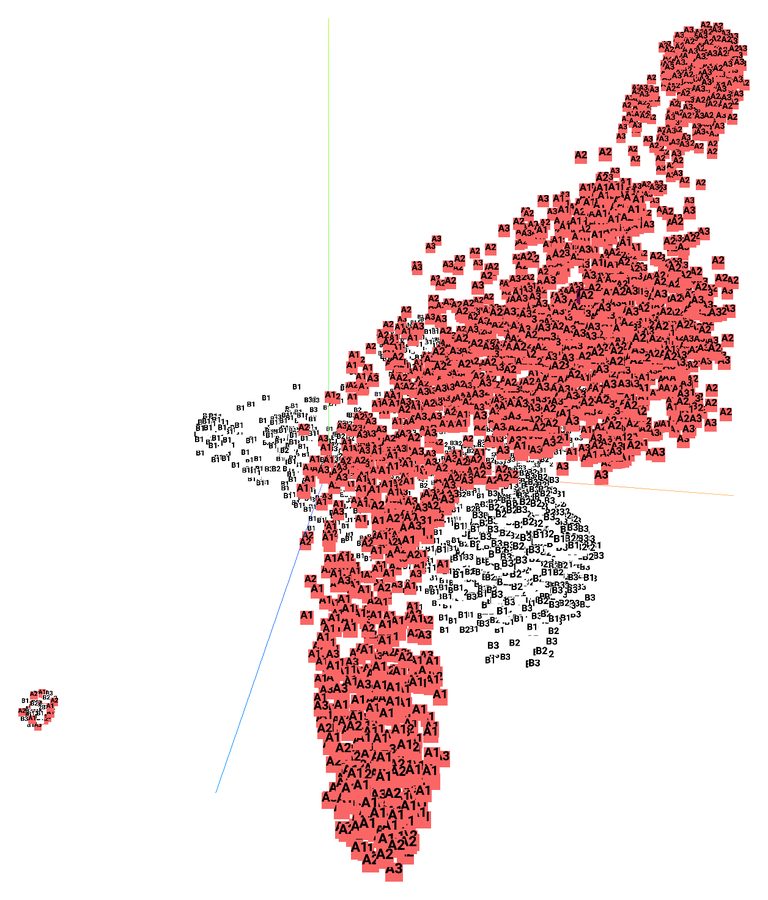
GDI-I³: three knobsIts visited states, in red, spread over more of the map.
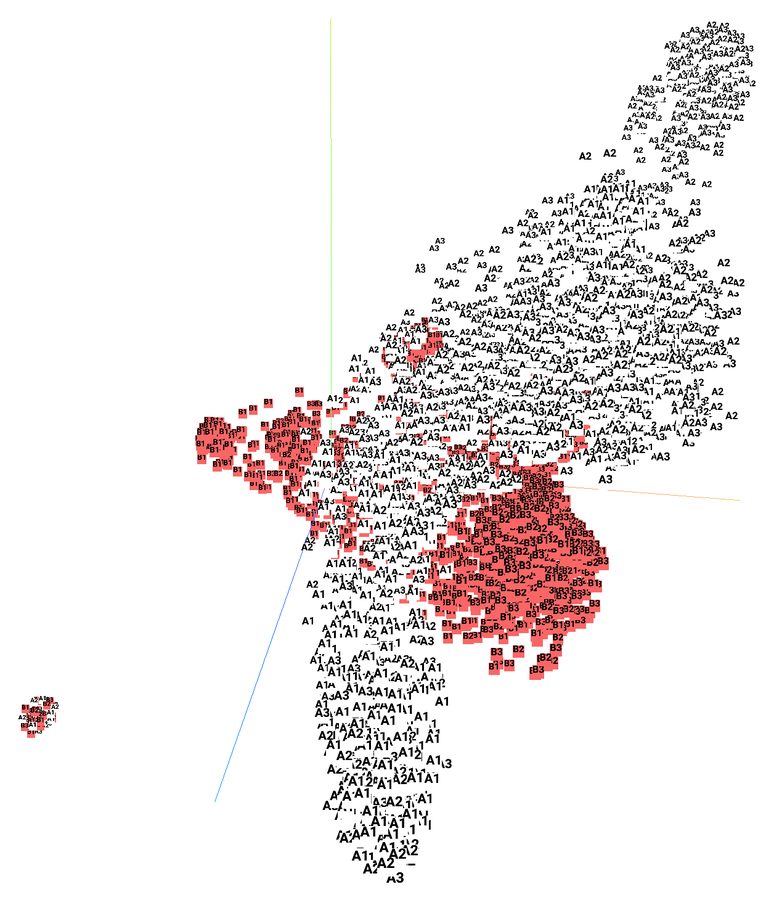
GDI-I¹: one knobIts visited states, in red, gather in a smaller region.
Left: normalized by GDI-I³, as drawn in the paper’s ablation figure. Right: the paper’s t-SNE of 6k Seaquest states from three stages of training.
More kinds of behavior give richer data, and richer data gives a stronger agent.
Why it matters
GDI turns the choice of behavior policies into a learnable part of reinforcement learning, with a framework, a proof and a recipe.
DQN, R2D2, LASER, PBT, Agent57 and Go-Explore become special cases, which makes each easier to understand.
With a few assumptions, optimizing the data distribution is proven never to hurt the RL update it feeds.
All of it on one GPU and one CPU, from the equivalent of weeks of human play.
The film
Opens the film page.
Cite
International Conference on Machine Learning (ICML 2022): PMLR · PDF · arXiv. An earlier version appeared at the AAAI-22 Workshop on Reinforcement Learning in Games.
@InProceedings{pmlr-v162-fan22c,
  title     = {Generalized Data Distribution Iteration},
  author    = {Fan, Jiajun and Xiao, Changnan},
  booktitle = {Proceedings of the 39th International Conference on Machine Learning},
  pages     = {6103--6184},
  year      = {2022},
  editor    = {Chaudhuri, Kamalika and Jegelka, Stefanie and Song, Le and Szepesvari, Csaba and Niu, Gang and Sabato, Sivan},
  volume    = {162},
  series    = {Proceedings of Machine Learning Research},
  month     = {17--23 Jul},
  publisher = {PMLR},
  pdf       = {https://proceedings.mlr.press/v162/fan22c/fan22c.pdf},
  url       = {https://proceedings.mlr.press/v162/fan22c.html}
}